$PHA Catalyst Posts
July 02, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $PHA Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
5 source posts analyzed· 2026-07-02T22:04:27+00:00Blackwell changes the confidential AI performance story. On B300, BF16 matmul under GPU-CC runs at 0.998x. A 96,000-matmul CUDA graph runs at 1.0012x. Paper by @bgmshana and Kevin Wang: arxiv.org/abs/2606.23969
· 2026-07-02T20:45:11+00:00Open Notebook brings NotebookLM-style research notebooks to self-hosted AI. Phala keeps sources, notes, prompts, and app state inside a TEE CVM. Deploy: cloud.phala.com/templates/open …
AI visual analysis: The image is a Phala Cloud "Template spotlight" promotional card featuring Open Notebook, highlighting its 25,979 GitHub stars and directing users to deploy at cloud.phala.com/templates/open-notebook, which aligns with the post about running NotebookLM-style research notebooks in a confidential TEE CVM.
· 2026-07-02T08:29:51+00:00Just came to know about this! Sold my $PHA bag as well. Accumulated more $W and $AVAX
· 2026-07-02T22:04:31+00:00GPU-local work is close to native. The cost shows up at the boundary. B300 H2D one-context transfer falls to 0.203x. D2H falls to 0.211x. Multi-context copies recover part of the bandwidth, but the bridge remains scarce.
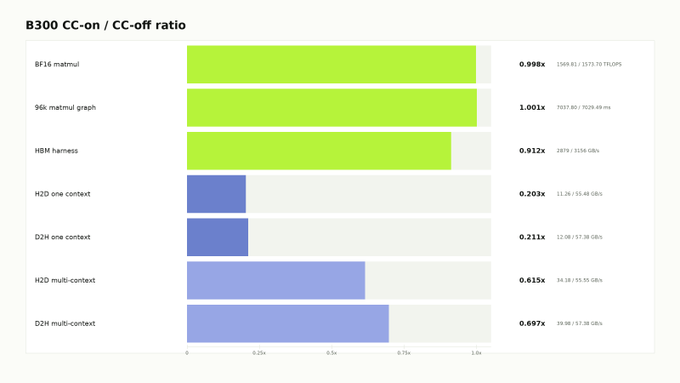
AI visual analysis: Bar chart titled 'B300 CC-on / CC-off ratio' showing performance metrics: BF16 matmul (0.998x), 96k matmul graph (1.001x), HBM harness (0.912x), H2D one context (0.203x), D2H one context (0.211x), H2D multi-context (0.615x), and D2H multi-context (0.697x).
· 2026-07-02T22:04:35+00:00The tax is workload-shaped. Rate-capped GPT-OSS-120B serving lost 1.1%. Dense decode lost 13-14%. MoE decode lost 24.7-27.6%. KV restore TTFT rose 131%. Ask what crosses the bridge, and how often.
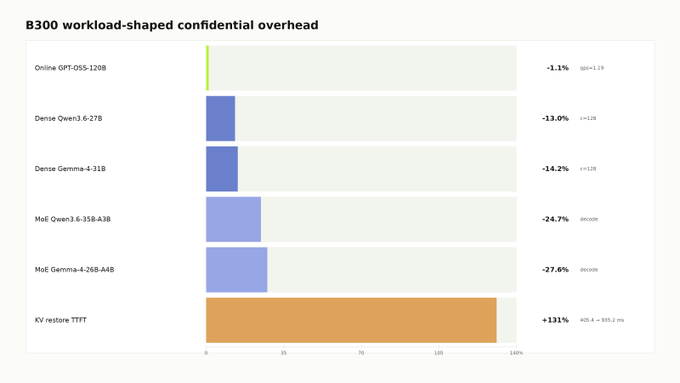
AI visual analysis: Bar chart titled 'B300 workload-shaped confidential overhead' comparing various models: Online GPT-OSS-120B (-1.1%), Dense Qwen3.6-27B (-13.0%), Dense Gemma-4-31B (-14.2%), MoE Qwen3.6-35B-A3B (-24.7%), MoE Gemma-4-26B-A4B (-27.6%), and KV restore TTTT (+131%).