$OPUS Catalyst Posts
August 23, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $OPUS Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
1 source posts analyzed· 2026-08-23T18:08:20+00:00we have opus 4.6 at 360 tps on a 5090 and you're blackpilling
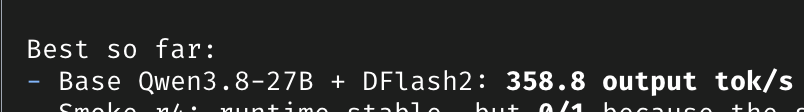
AI visual analysis: The image shows a benchmarking log entry reading "Best so far: - Base Qwen3.8-27B + DFlash2: 358.8 output tok/s", which relates to the post by showing a comparable 27B model's inference speed of ~359 tokens/second, just shy of the mentioned 360 tps figure on a 5090—undermining the claim that the cited speed is impressive or noteworthy.