$IOTX Catalyst Posts
October 05, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $IOTX Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
3 source posts analyzed· 2026-10-05T16:06:16+00:00Any open model, from anywhere, running on your own Mac, plugged straight into your agents. Rapid-MLX 0.15.6: • Point it at any Hugging Face checkpoint and it serves it • One command to wire local models into Codex, Claude Code and more • Typed, on-device decisions
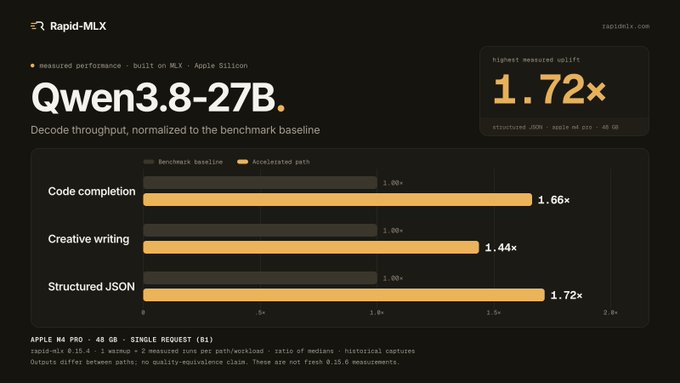
AI visual analysis: The image is a benchmark chart for Rapid-MLX showcasing a **1.72× highest measured uplift** in decode throughput for the Qwen3-27B model running on an Apple M4 Pro (48 GB) via Single Request (R1) mode, with task-specific gains of **1.66× for code completion**, **1.44× for creative writing**, and **1.72× for structured JSON** output relative to a benchmark baseline. This visually reinforces the post's claim that Rapid-MLX delivers high-performance, on-device inference for open models running locally on Apple Silicon Macs.
· 2026-10-05T19:10:57+00:00An early glimpse of something we've been working toward. Local AI on a Mac has always served one person, its owner. With Share Compute, @rapidmlx and @qspro_ai are testing whether that same Mac can serve real API traffic for others. First numbers look promising: a Mac mini (M4
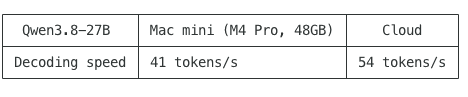
AI visual analysis: A comparison table showing decoding speeds: 'Qwen3.8-27B' on 'Mac mini (M4 Pro, 48GB)' at '41 tokens/s' versus 'Cloud' at '54 tokens/s'.
· 2026-10-05T19:08:36+00:00We're so back Still day 1