$IOTX Catalyst Posts
September 04, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $IOTX Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
2 source posts analyzed· 2026-09-04T23:55:20+00:00Local AI is advancing faster than anyone expected. When an everyday Mac Mini running on @rapidmlx delivers output quality matching an H100 cloud cluster, the marginal cost of AI approaches zero—breaking Big Tech’s monopoly on compute and data. Local Compute + Distributed

AI visual analysis: A split comparison showing two origami cranes on wet black slate: the left, labeled "fal [H100] - inference 0.39s · end-to-end 1.0s," and the right, labeled "Mac mini M2 Pro · 52s end-to-end," visually demonstrating the post's claim that local AI on consumer hardware can match the output quality of H100 cloud clusters, though at slower speeds.
· 2026-09-04T12:03:36+00:0034.85 tokens per second on Apple Silicon. ⚡️ That’s Rapid-MLX, built by IoTeX, now running Qwen3.8-Flash-Next locally with a 262K-token context window and 45/45 evaluation checks passed. The future of local AI is shipping. $IOTX
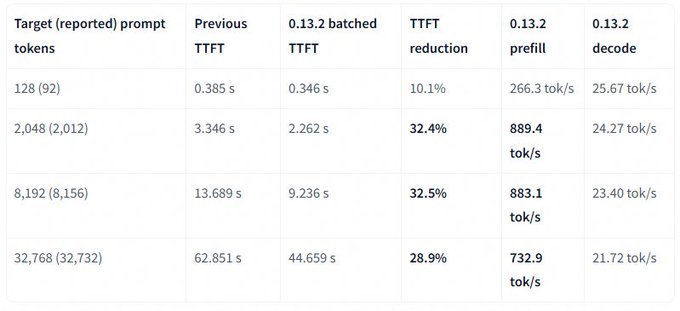
AI visual analysis: A performance comparison table showing TTFT (Time To First Token) metrics across different prompt token sizes (128, 2,048, 8,192, 32,768), comparing previous TTFT against 0.13.2 batched TTFT, showing reduction percentages of 10.1%, 32.4%, 32.5%, and 28.9% respectively, along with prefill and decode tok/s rates.