$GPU Catalyst Posts
July 03, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $GPU Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
1 source posts analyzed· 2026-07-03T21:04:00+00:001/ We published our first technical report today. We ran a 229B model split across five consumer GPUs in five countries over the public internet and measured 12.6 tok/s interactive, 194 tok/s batched. With cryptographic receipts on every request. doi.org/10.5281/zenodo …
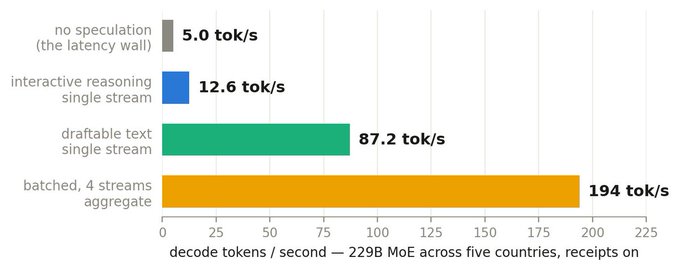
AI visual analysis: A horizontal bar chart titled "decode tokens / second — 229B MoE across five countries, receipts on" compares throughput across four scenarios: no speculation (the latency wall) at 5.0 tok/s, interactive reasoning single stream at 12.6 tok/s, draftable text single stream at 87.2 tok/s, and batched, 4 streams aggregate at 194 tok/s. The chart visually summarizes the performance benchmarks highlighted in the technical report announcement, showing how speculative decoding and batching dramatically increase tokens-per-second output for the 229B Mixture-of-Experts model distributed across consumer GPUs.