$GLM Catalyst Posts
September 23, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $GLM Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
7 source posts analyzed· 2026-09-23T12:05:43+00:00
· 2026-09-23T12:18:43+00:00We really appreciate all you have done to support us and the wider community @only01Essential
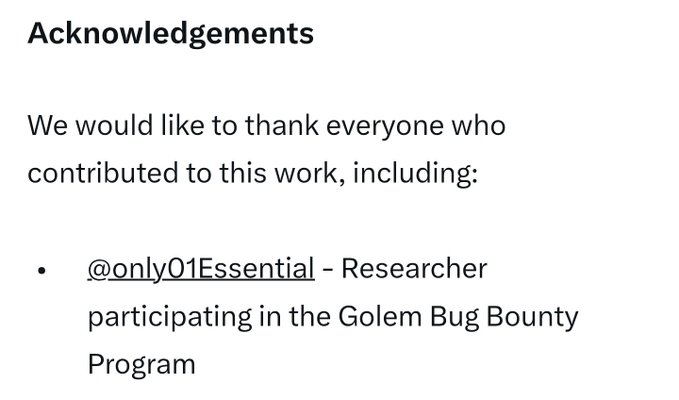
AI visual analysis: An acknowledgements section thanking @only01Essential as a Researcher participating in the Golem Bug Bounty Program.
· 2026-09-23T13:42:08+00:00Thank you @0xpessimist - we wanted to be transparent with the full 3rd party report so everyone can see for themselves the findings (link in the article pinned to our X handle)
· 2026-09-23T00:26:14+00:00GLM inspired coffee fueled from Tokenmaxxing @thatcofffeeguy . Support the community
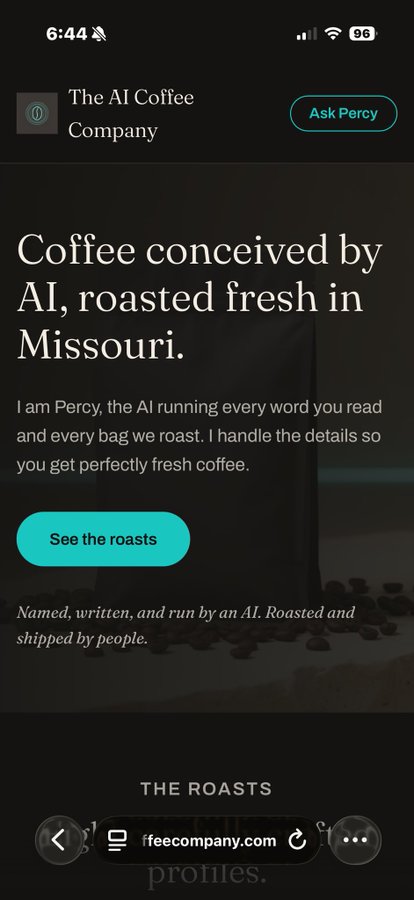
AI visual analysis: Mobile screenshot of "The AI Coffee Company" website stating "Coffee conceived by AI, roasted fresh in Missouri," introducing Percy the AI with an "Ask Percy" button and "See the roasts" option.
· 2026-09-23T23:03:17+00:00is it better to put GLM accross 4 sparks?
· 2026-09-23T15:00:11+00:00GLM 5.3 Flash on 4 x CMP 170HXs. More optimisations. I repeat, 4 of these cards cost less than 2 DGX Sparks. Benchmark courtesy of localmaxxing by @LottoLabs
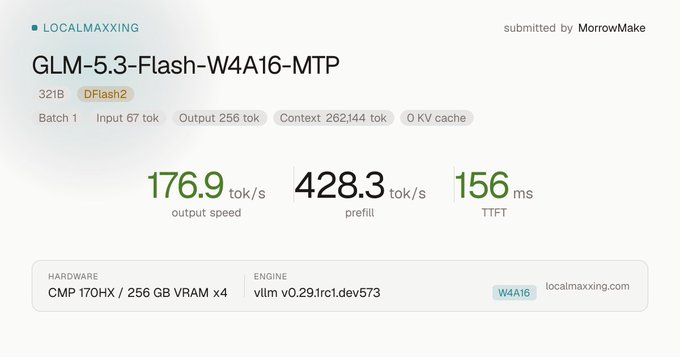
AI visual analysis: A performance benchmark report for GLM-5.3-Flash-W4A16-MTP by MorrowMake showing output speed of 176.9 tok/s, prefill of 428.3 tok/s, and TTFT of 156 ms, running on CMP 170HX hardware with vllm engine.
· 2026-09-23T13:33:54+00:00See you there!