$GLM Catalyst Posts
September 17, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $GLM Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
3 source posts analyzed· 2026-09-17T21:28:18+00:00kimi and deepseek fans, your model is already in bolt, one click, no setup, no api keys four open models are in the picker for 11m+ builders, and you can run any of them on a real project glm 5.3 flash is leading the usage so far with up to 50x usage on flash, the rest are
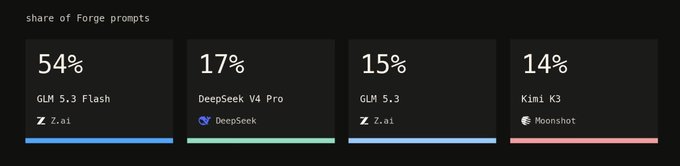
AI visual analysis: The image shows a dashboard titled "share of Forge prompts" displaying the usage distribution across four open-source AI models: GLM 5.3 Flash leads with 54% (Z.ai), followed by DeepSeek V4 Pro at 17%, GLM 5.3 at 15% (Z.ai), and Kimi K3 at 14% (Moonshot), illustrating the model usage statistics mentioned in the accompanying post about open models being available in the Bolt picker.
· 2026-09-17T15:35:58+00:00Early RSI signs! Apparently GLM-5.3 helped build the inference stack serving GLM 5.3-Flash. That meant working across 100k+ Chinese accelerators, 1M context, immature kernels, and barely any docs. Still, it helped take the system from first successful run to production in
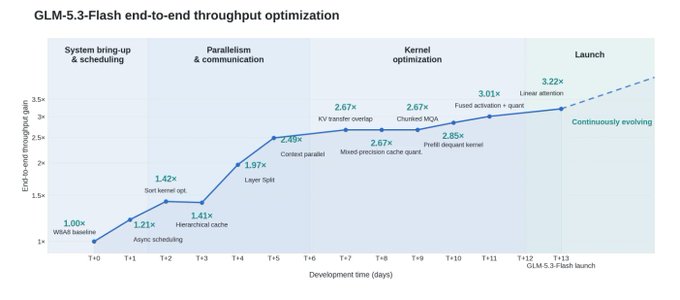
AI visual analysis: A line graph titled 'GLM-5.3-Flash end-to-end throughput optimization' showing performance gains from 1.00x to 3.22x across development milestones T+0 to T+13, covering phases from MRAM baseline to GLM-5.3-Flash launch.
· 2026-09-17T02:43:45+00:00GLM