$GLM Catalyst Posts
August 29, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $GLM Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
15 source posts analyzed· 2026-08-29T07:36:53+00:00Got my first 0click. Reported! Just ME and GLM-5.3 on my mac ultras
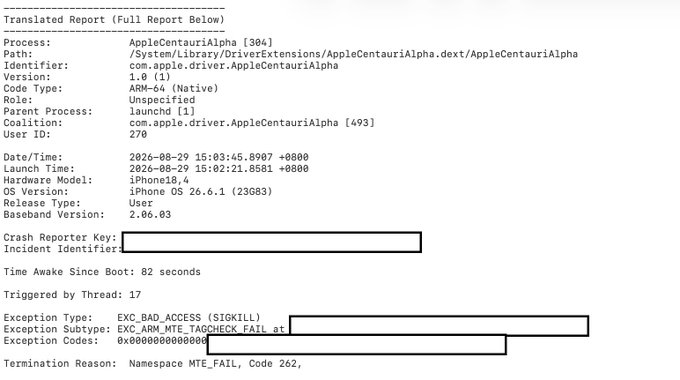
AI visual analysis: An Apple crash report for the "AppleCentauriAlpha" process showing a SIGKILL EXC_BAD_ACCESS exception with termination reason "Namespace MTE_FAIL, Code 262" on iPhone OS 26.6.1, which appears to document the 0-click exploit the user mentioned between "ME" and "GLM-5.3." The "0x0000000000000000" exception codes (redacted in the image) and MTE (Memory Tagging Extension) failure indicate the crash was triggered by a memory safety violation exploited remotely.
· 2026-08-29T20:13:38+00:00update: i tried claiming the 300M GLM-5.3-Flash tokens again tonight. the button kept loading for ages, then finally gave me: “Claim failed. Today’s quota has been exhausted. Try again tomorrow.” looks like the promo is getting slammed with traffic. 300M free tokens and
AI visual analysis: A screenshot shows a "Claim failed" error message popup on a dark-themed website, with the body text reading "Claim failed. Please try again later." The image illustrates the user's experience of attempting to claim the 300M GLM-5.3-Flash tokens promo and encountering the error described in the post, though the specific quota exhaustion message mentioned in the caption is not visible in this particular popup.
· 2026-08-29T02:15:00+00:00Ox Alpha was GLM-5.3 Flash all along and it is now free on three platforms, approaching Opus 4.8 on coding with 320B total parameters, 1M context and MIT open weights at $0.

· 2026-08-29T01:11:02+00:00GLM-5.3 is now available on the Qtum AI Router. This is an interesting model because apparently it did a ninja "free" launch as 0xAlpha and served trillions of tokens. Various benchmarks score this model quite high, a lot better than GLM-5.2. @Zai_org

AI visual analysis: A dark-themed leaderboard interface showing AI models from 'Zhipu AI', including 'glm-5.3-volo', 'glm-5.2', 'glm-5.2-volo', and 'glm-5.1', ranked by input, output, context, and rank out metrics.
· 2026-08-29T14:47:33+00:00GLM 5.3 Flash abliterated EXL3
· 2026-08-29T02:08:22+00:00Personally used over a billion GLM 5.3 tokens. Wish the latency was a bit better but coding throughput and value is outstanding.

AI visual analysis: A dark green blurred background displays white text announcing "GLM-5.3 WEIGHTS ARE OPEN," with smaller text below listing "Coding · Agentic · Cyber" capabilities. The image serves as a promotional graphic supporting the post's claim about extensive hands-on experience with GLM 5.3 tokens, emphasizing the model's open availability and its strengths in coding and agentic tasks.
· 2026-08-29T02:11:11+00:00GLM 5.3 is an amazing model. Maybe we should include it in our Nansen subscription? Would be cool to use Nansen as an inference provider in Hermes, OpenClaw etc. RT if you want this in your Nansen sub!
· 2026-08-29T14:06:35+00:00gm sers openai cut cursor off from its models today. anthropic's head of compute says they won't do the same meanwhile unsloth shrank GLM-5.3 from 1.51TB to 239GB, 2-bit, ~81% of the accuracy, running local an api key is a lease. weights on disk are not
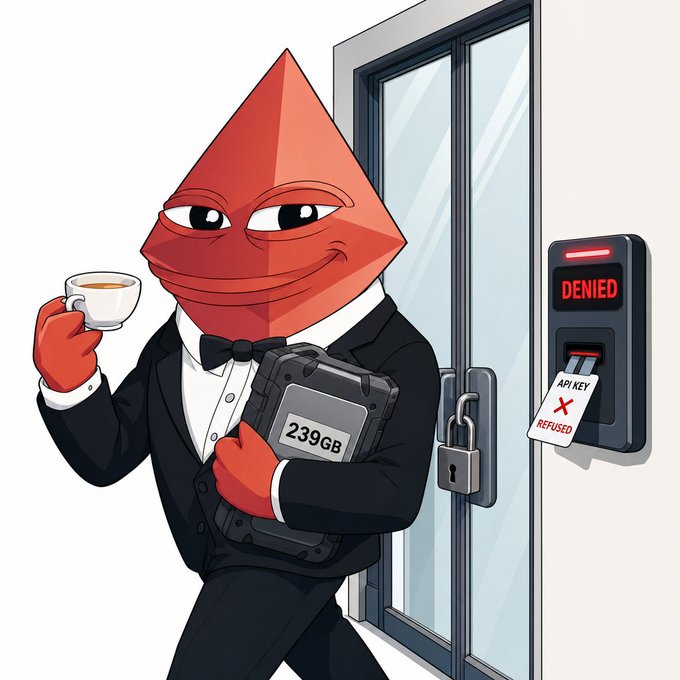
AI visual analysis: A cartoon illustration depicts a diamond-shaped red character in a tuxedo holding a '239GB' hard drive and a coffee cup, standing next to a door with a 'DENIED' sign and an 'API KEY REFUSED' tag.
· 2026-08-29T13:44:05.313000+00:00My agent just build his own graphify vor 2 cents :D ..glm 5.3 flash is insane :D ..he also created a skill, that he uses it, + it auto rebuild with git ..and i didnt do s* :D
· 2026-08-29T17:43:12+00:00GLM-5.3 eleva la programación de frontera y revela capacidades cibernéticas emergentes
AI visual analysis: A cartoon depicts a hooded figure labeled with a speech bubble saying "¡Arreglando el bug!" standing near a vault labeled "Bóveda Digital" and a screen reading "Vulnerabilidades," while another surprised character watches. The overlaid Spanish text "GLM-5.3 eleva la programación de frontera y revela capacidades cibernéticas emergentes" appears in the lower-left corner, with "B" logos in the upper-right, tying the humorous cybersecurity scene to the announcement about GLM-5.3's emerging cyber capabilities.
· 2026-08-29T15:31:35+00:00GLM-5.3 at 41.8% on Terminal-Bench 4.0 is probably the clearest sign yet that open weights are no longer living in a separate capability tier. It’s ahead of GPT-5.6 Sol, Opus 4.8 and Grok 4.6 here, with only Opus 5 and Fable 5 still clearly above it. Once an open model gets

AI visual analysis: A benchmark ranking chart showing AI coding models with GLM-5.3 (max) highlighted in a red box at rank 3 with 41.8% ± 3.2% resolution rate using Claude Code, below Opus 5 and Fable 5.
· 2026-08-29T04:22:36+00:00GLM 5.3 > Grok 4.6 > GPT 5.6 Luna
· 2026-08-29T16:50:46+00:00GLM 5.3 is the king of the hill

AI visual analysis: An elaborate fantasy illustration shows various AI models depicted as warriors holding flags atop a mountain peak, including 'KIMI K3 ABLE ASCEND', 'GLM-5.3 KING OF THE HILL', and 'QWEN 3.8 CLIMBING'.
· 2026-08-29T05:08:13+00:00Dspark vs DFlash 2 - which one works best for GLM5.3?
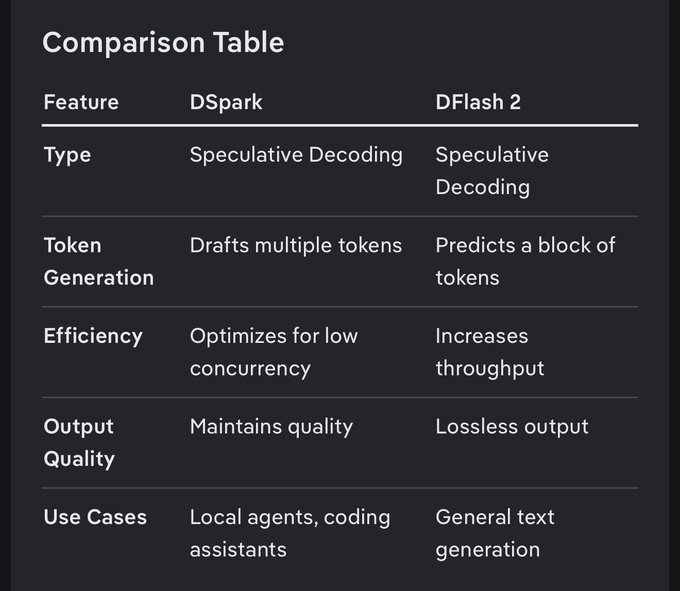
AI visual analysis: A comparison table on a dark background contrasts features of 'DSpark' and 'DFlash 2', listing their Type, Token Generation, Efficiency, Output Quality, and Use Cases.
· 2026-08-29T18:52:58+00:00GLM-5.3-Flash EXL3-3.0bpw by @0xSero @BrandonMusicKy @LottoLabs @localmaxxing 193.8 tk/s
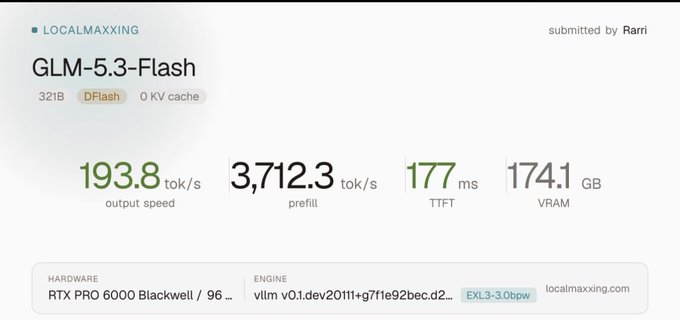
AI visual analysis: A performance benchmark result for 'GLM-5.3-Flash' showing 193.8 tok/s output speed, 3,712.3 tok/s prefill, 177 ms TTFT, and 174.1 GB VRAM on RTX PRO 6000 Blackwell hardware.