$GLM Catalyst Posts
August 28, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $GLM Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
16 source posts analyzed· 2026-08-28T02:12:26+00:00first full day of GLM being paid and deepseek immediately took back the throne muse spark is a sleeper hit, right on its tail
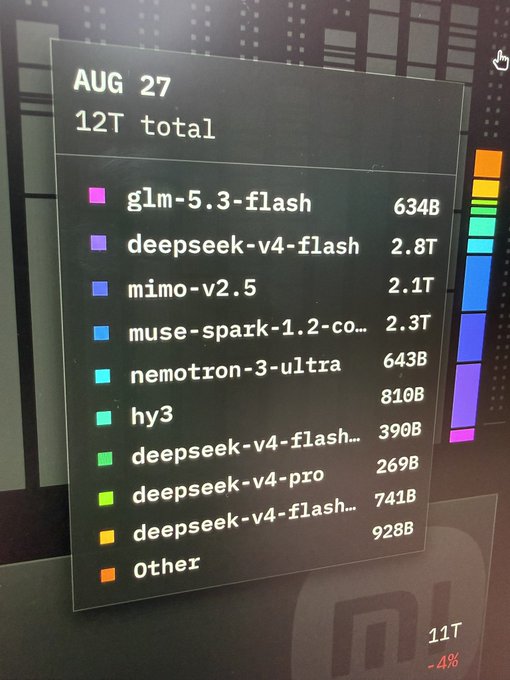
AI visual analysis: A data dashboard from August 27 shows total volume of 12T, with DeepSeek variants dominating the rankings—deepseek-v4-flash leading at 2.8T, followed by muse-spark-1.2-com at 2.3T and mimo-v2.5 at 2.1T, while GLM-5.3-flash trails at 634B. The chart illustrates the post's point that despite GLM's first paid day, DeepSeek reclaimed the top spot, with Muse Spark emerging as a strong contender behind it.
· 2026-08-28T21:12:44+00:005.6-luna with 80% discount and still 5x more expensive than GLM.. gosh I love open models :D
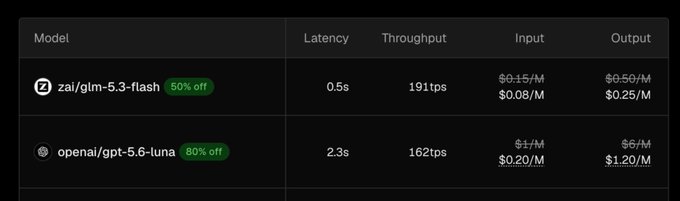
AI visual analysis: A pricing comparison table shows zai/glm-5.3-flash (50% off) at $0.15/M input with 0.5s latency and 191tps throughput, versus openai/gpt-5.6-luna (80% off) at $1/M input with 2.3s latency and 162tps throughput. The image supports the post's point that despite GPT-5.6-luna's hefty 80% discount, it still costs roughly 5x more than the open-source GLM model, which also delivers faster latency and higher throughput.
· 2026-08-28T12:07:59+00:00Bro, Zcode update is here, you can directly claim 300 million Tokens now! Effective Friday 20:00 Expires next Monday 09:00 Perfect for testing the 3D capabilities—heard GLM-5.3-Flash + Blender delivers killer 3D effects.
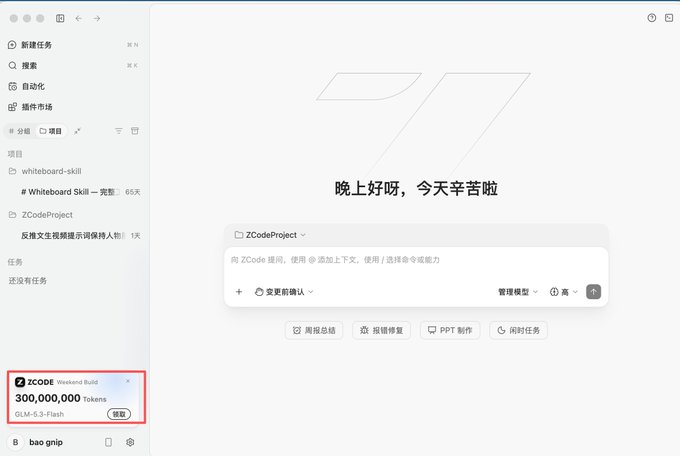
AI visual analysis: The image shows a ZCode interface with a sidebar highlighting "ZCODE Weekend Build 300,000,000 Tokens" featuring GLM-5.3-Flash, while the main chat displays the greeting "晚上好呀,今天辛苦啦" (Good evening, you've worked hard today) with task options. The red-boxed promotion in the bottom left corner directly advertises the 300 million token weekend giveaway mentioned in the post, connecting the visual UI notification to the promotional campaign.
· 2026-08-28T15:38:13+00:00B300s secured, GLM-5.3 will run everywhere.
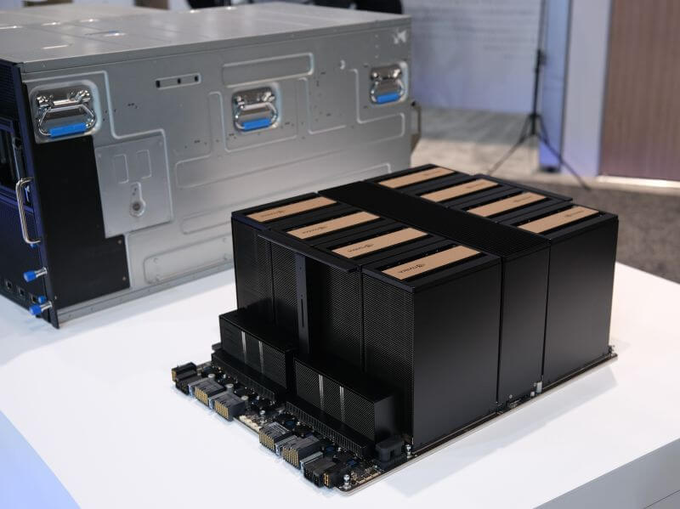
AI visual analysis: A rack-mounted server chassis sits behind a baseboard populated with multiple upright NVIDIA B300 GPU modules on a white display table, showcasing the hardware ready for deployment. The accompanying caption emphasizes that B300s are secured and the GLM-5.3 model will run across this infrastructure.
· 2026-08-28T03:39:25+00:00Ox Alpha Identity Revealed: GLM-5.3 Flash. Z. ai Founder Jietang Announces: AA Score of 57, priced at 1/100th of frontier models, fully powered by domestic chips. It holds nearly 20% of the weekly Token share on OpenRouter, ranking first, and has propelled Z .ai's overall share
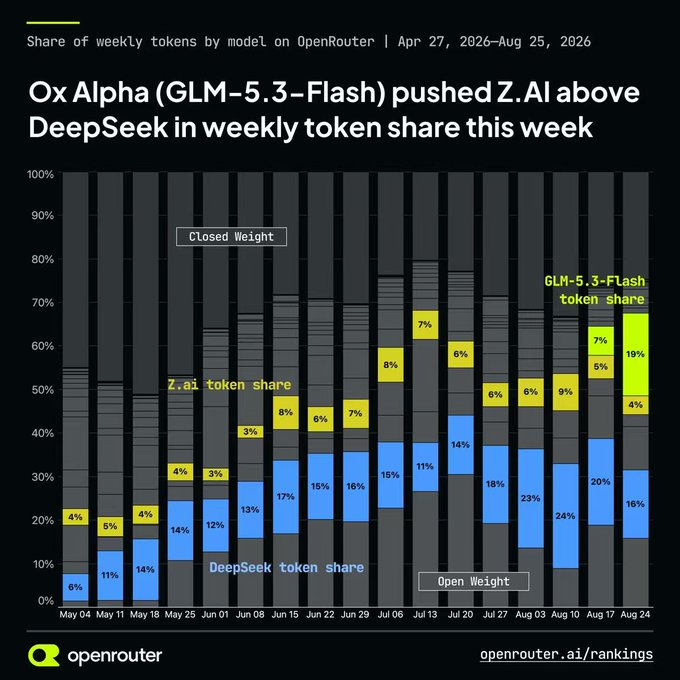
AI visual analysis: The image is a stacked bar chart from OpenRouter showing the weekly token share by model from April 27 to August 25, 2026, highlighting how Z.ai's overall share rose above DeepSeek's this week, with the new GLM-5.3-Flash ("Ox Alpha") capturing 19% of weekly tokens and Z.ai's total share reaching 24%.
· 2026-08-28T11:29:47+00:00This is real! Download Zcode, and you can claim 300 million tokens for Weekend Build. Now you can enjoy GLM5.3-Flash to your heart's content. Picking up this freebie isn't impossible either.
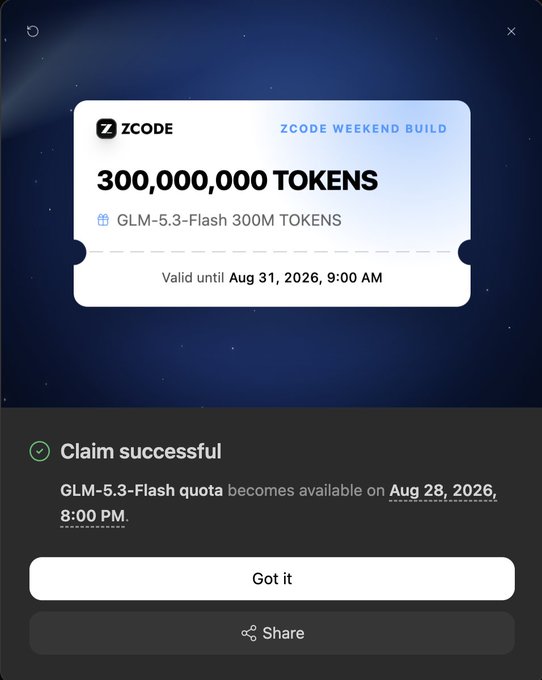
AI visual analysis: The image shows a successful claim confirmation for 300,000,000 ZCODE Weekend Build tokens, valid until Aug 31, 2026, 9:00 AM, with GLM-5.3-Flash quota becoming available on Aug 28, 2026. This confirms the post's claim that downloading Zcode allows users to claim 300 million free tokens for use with the GLM-5.3-Flash model.
· 2026-08-28T22:14:13+00:00I told you to expect improvements didn't I? Major GLM-5.3 Flash update for 2x DGX Sparks - Full native 1M context - 1,754,237 FP8 KV cache - Fixed *major* concurrency issues - Same excellent EXL3 quant Once again, expect more improvements. Get it here:
· 2026-08-28T17:32:26+00:00GLM 5.3 Flash is live on Phala—served inside a TDX-attested GPU TEE. Private, verifiable inference for coding, long-horizon agents, visual understanding. phala.com/models/z-ai/gl …
AI visual analysis: A promotional graphic for 'PHALA' featuring the 'GLM 5.3 Flash' model, with the tagline 'Private, verifiable inference.' and the website 'phala.com' at the bottom.
· 2026-08-28T23:29:10+00:00Watching GLM 5.3 Flash reverse engineer stuff for you is fun btw
· 2026-08-28T21:34:49+00:00Ox Alpha GLM 5.3-flash on the phone via the z ai subscription
AI visual analysis: A dark, blurred green background with white text reading 'GLM-5.3 WEIGHTS ARE OPEN' and a 'Coding · Agentic · Cyber' tagline.
· 2026-08-28T12:57:08+00:00Sorry, did you say 250 submissions?
· 2026-08-28T18:03:08+00:00and while I am busy with my day job... my Hermes are busy standing up the GLM-5.3 Flash EXL3 for 2x DGX Sparks recipe from @MiaAI_lab Really excited for this as I think it will become our new daily driver
AI visual analysis: A screenshot of a Discord chat interface showing multiple server channels and messages discussing blockchain technology and #WL and infrastructure.
· 2026-08-28T18:31:48.748000+00:00Aggregate GLM 5.3 vs 5.3 flash benchmarks are extremely close Suggested
· 2026-08-28T02:23:50+00:00DFlash 2 for GLM 5.3 Flash dropped, and it's a significant step forward. I already have it running on all four of my DGX Sparks, and I have the numbers everyone is about to debate. The headline making the rounds is 2.8× faster. That's true, but it's versus plain
· 2026-08-28T16:37:17+00:00Day Zero - Already Running it GLM-5.3-Flash just landed AND it is already available on @ionet via @OpenRouter , just hours after launch. 320B total parameters → 18B active That is a serious model, but built for flash-tier economics - speed and real-world agent workflows.
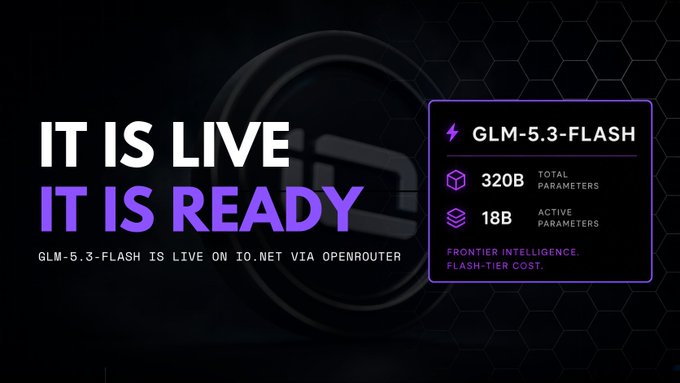
AI visual analysis: A promotional graphic announcing 'IT IS LIVE IT IS READY' for GLM-5.3-FLASH, featuring a design with purple accents and highlighting 320B total parameters and 18B active parameters.
· 2026-08-28T10:32:13+00:00GLM-5.3-Flash sounds dope