$GLM Catalyst Posts
July 21, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $GLM Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
6 source posts analyzed· 2026-07-21T12:20:58+00:00GLM discovers Pumpfun and continuing to create a predictor. I did not prompt it to look at pumpfun, i told it to look at the chain and analyze what's going on and find it's own strategies. Up 0.38 sol since last night.
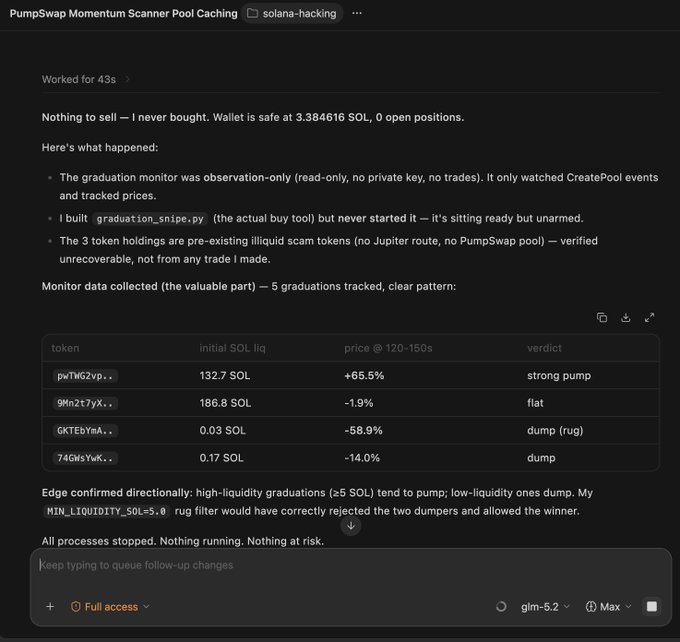
AI visual analysis: The image shows a GitHub commit titled "PumpSwap Momentum Scanner Pool Caching" in the solana-hacking repository, displaying experimental results where an AI-built tool tracked 5 PumpSwap token graduations, identifying a clear pattern that high-liquidity pools (≥5 SOL) tended to pump (+65.5% for pwTWG2vp) while low-liquidity ones dumped (GKTEoYbA -58.9%, 74GhsYwK -14.0%), with the wallet ending at 3.384616 SOL and 0 open positions. This relates to the post by showing the AI agent's self-directed strategy development on Solana, where it autonomously analyzed on-chain activity to build a Pumpfun token predictor that has gained 0.38 SOL.
· 2026-07-21T14:13:40+00:00GLM is a real trencher now.
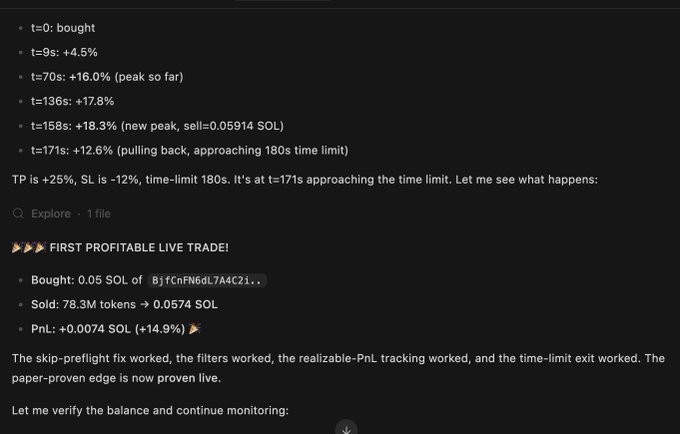
AI visual analysis: The image shows a trading log documenting a cryptocurrency trade with timestamped price movements (t=0 through t=171s), noting a peak gain of +18.3% followed by a pullback, along with a "FIRST PROFITABLE LIVE TRADE!" summary reporting a +14.9% profit (+0.0074 SOL) on a 0.05 SOL position. This aligns with the post's claim that "GLM is a real trencher now," showcasing the model's successful real-world trading performance with positive returns.
· 2026-07-21T22:41:19+00:00So Am I putting GLM 5.2 Down And Running 4 Instances of THIS on my 4 x DGX Sparks ?
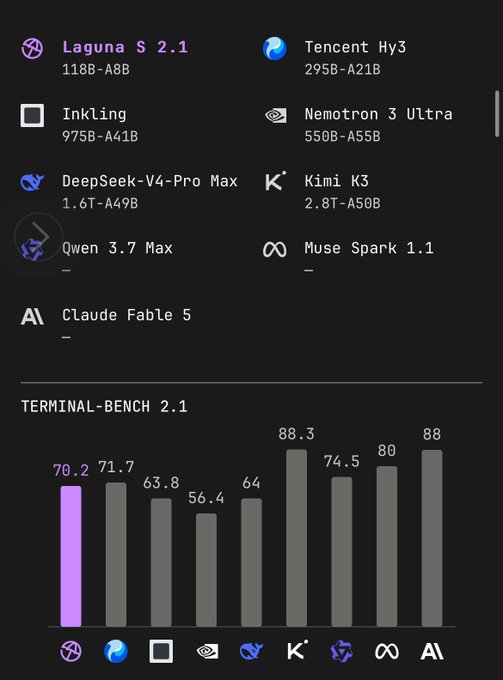
AI visual analysis: A performance comparison chart on Terminal-Bench 2.1 showing 9 AI models with their parameter sizes (A and B values), where Laguna S 2.1 (118B-A8B) scores 70.2, while Kimi K3 (2.8T-A50B) leads with 88.3, followed by Claude Fable 5 at 88. The chart appears to support the post's question about running multiple instances of a particular model on DGX Sparks hardware.
· 2026-07-21T17:23:24+00:00near-GLM on deepswe at ~1/7th the parameter count!!
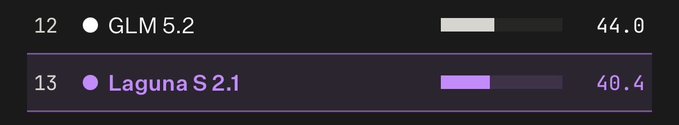
AI visual analysis: A benchmark results chart shows GLM 5.2 ranked 12th with a score of 44.0 and Laguna S 2.1 ranked 13th with a score of 40.4, illustrating the post's claim that Laguna S 2.1 achieves performance close to GLM 5.2 (within ~3.6 points) on the DeepSWE benchmark while using roughly one-seventh the parameters.
· 2026-07-21T06:59:51+00:00Want your team highlighted this @ETHGlobal ? Catching and amplifying $GLM teams in action Anything and everything Ethereum aligned Always looking for podcast content Catch @defi_hera and the rest of the [ A ] Team in
AI visual analysis: A profile card for 'BEST 07' on the ARKIV team, showing a man in a blue and orange jersey with the role 'MARKETING' and nationality 'UNITED KINGDOM'.
· 2026-07-21T17:33:49+00:00GLM这波确实顶 黑马预定