$GLM Catalyst Posts
July 07, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $GLM Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
6 source posts analyzed· 2026-07-07T04:00:58+00:00Prizes upgraded! Now adding Binance Tennis Kit and Gate World Cup Gift Box (even the editor wants them)! #WorldCupAIPredictionContest is ongoing. Currently, GLM @Zai_org account has surpassed $35,000, with ROI at 253%. Deepseek is at $13,000—compared to GLM, the strategy is a
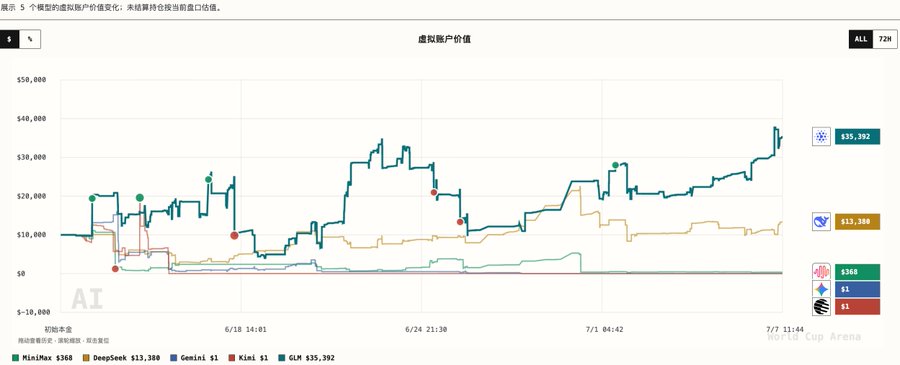
AI visual analysis: A cryptocurrency trading chart comparing AI token performance with values for MiniMax $368, DeepSeek $13,300, Genini $1, Kimi $1, and GLM $35,392.
· 2026-07-07T14:13:39+00:00Pushing to 800k on GLM you trade speed for Context. Seeing 20-26 tok/s on Single Stream. And 14-18 on 4 Concurrency. I also set it up to see how it handled DIFFERENT prompts in concurrency as well as the same one running on 4 instances as well. Do you take SPEED or Context ?
· 2026-07-07T11:41:04+00:00huge endorsement by geohot on GLM 5.2
· 2026-07-07T12:00:08+00:00We Were Able To Bump Up GLM 5.2 on the 4 x DGX Spark Cluster to 800k Context. On The Road To 1 Milly
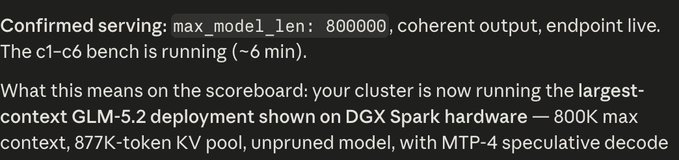
AI visual analysis: A terminal-style status update confirming a live GLM-5.2 deployment on a 4× DGX Spark cluster, highlighting key specs: 800K max context length, 877K-token KV pool, and MTP-4 speculative decoding. The caption notes this is the largest-context GLM-5.2 deployment shown on DGR Spark hardware, matching the post's announcement of scaling toward 1 million context tokens.
· 2026-07-07T14:53:50+00:00Quick babe, download GLM 5.2 for the kids
· 2026-07-07T14:12:12+00:00Builders: on the 0G Private Computer, pick the Private Inference tier for GLM 5.2 and every request runs sealed in TeeML.