$GLM Catalyst Posts
July 06, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $GLM Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
6 source posts analyzed· 2026-07-06T18:51:53+00:00Finally a new bench where GLM-5.2 crashes to mid-tier models
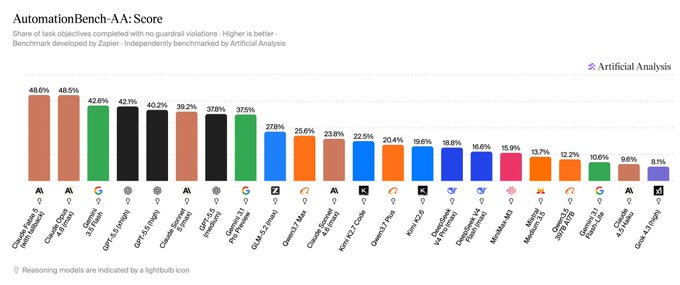
AI visual analysis: The image is a bar chart titled "AutomationBench-A A: Score," showing the percentage of task objectives completed without guardrail violations by various AI models, with top performers including Claude Opus 4.5 (High), Claude Opus 4.5 (Fast), and Gemini 3 Pro at 48.6%, 48.5%, and 42.6% respectively. The chart visually supports the post's claim that GLM-5.2 performs as only a mid-tier model, ranking 10th at 25.6%—well below top scorers like Claude Opus 4.5 (48.6%) and ahead of only smaller or weaker models such as Grok 4.5 (8.1%) and Claude Haiku 4.5 (10.6%).
· 2026-07-06T02:37:27+00:00I’ve been doing the math, If I can get 100 people paying ~$200/mo, I could rent an 8×MI325X (256gb) node serve private, fully uncensored GLM-5.2 with ~128K context in 4 bit at: Rough full-load math: • 10 active users: ~20 tok/s each • 50 active users: ~10 tok/s each Would
· 2026-07-06T08:07:30+00:00I see all those cool Fable games but I want to see more GLM-5.2 games now!
· 2026-07-06T12:15:30+00:00- GLM beating Anthropic Fable, - Hy3 beating GLM,
AI visual analysis: Small/blurry chart image showing multiple bar graphs with blue bars, appearing to be a data visualization dashboard with category labels at the bottom.
· 2026-07-06T00:58:23+00:00ionet gánh GLM-5.2 ok
· 2026-07-06T12:04:32+00:00Watch this release. We will have GLM5.2 running at much smaller sizes soon! Looking good Hy3
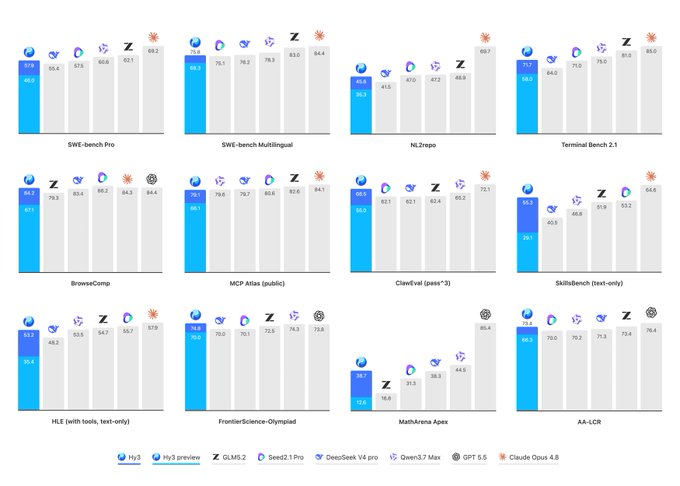
AI visual analysis: A benchmark chart comparing AI models (Hy3, Hy3 preview, GLM5.2, DeepSeek V4 pro, Qwen37 Max, GPT 5.5, Claude Opus 4.8) across datasets like SWE-bench Pro, NL2repo, and MathArena Apex.