$GLM Catalyst Posts
June 30, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $GLM Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
11 source posts analyzed· 2026-06-30T22:00:47+00:00Sorry if annoying but I really want to push that. GLM is not that far from Opus. If they can close the Fable gap, and that doesn't sound that insane anymore, everything changes. I'd go 100% OSS and never look back... Can we make that happen? What could I do to help that happen?
· 2026-06-30T17:09:21+00:00GLM's new harness - should it be just called Z Codex
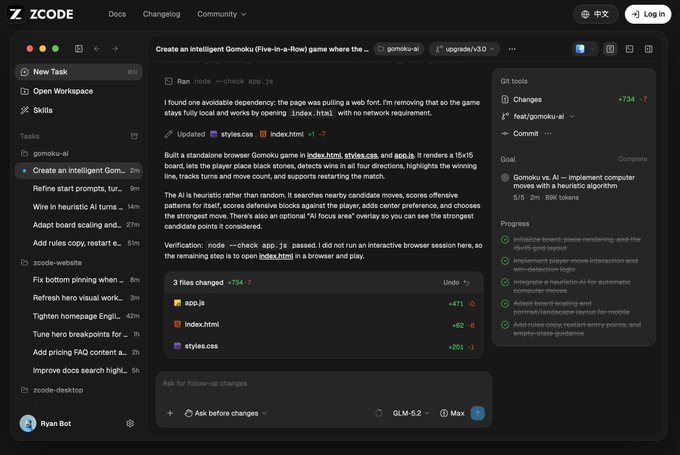
AI visual analysis: A screenshot of the ZCODE interface displays a coding session where an AI agent (running on the "glm-4.6" model, with "GLM-5.2 v" visible) is building a "Create an intelligent Gomoku" game, showing a diff of 734 changes (+7, -7) and a "Complete" goal. This demonstrates the new GLM-powered harness in action, supporting the post's suggestion that the platform should be called "Z Codex."
· 2026-06-30T22:36:48+00:00Let’s go GLM-5.2
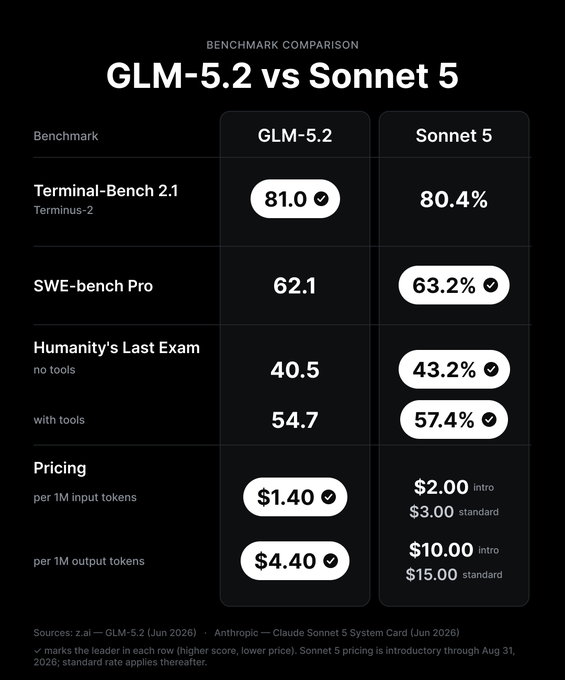
AI visual analysis: A benchmark comparison chart showing GLM-5.2 outperforming Sonnet 5 on Terminal-Bench 2.1 (81.0% vs 80.4%), matching on SWE-bench Pro (within 1.1%), and trailing on Humanity's Last Exam, while undercutting Sonnet 5's pricing on both input ($1.40 vs $2.00 introductory/$3.00 standard) and output tokens ($4.40 vs $10.00/$15.00)—supporting the post's "Let's go GLM-5.2" sentiment by highlighting the model's competitive coding performance at a significantly lower cost.
· 2026-06-30T18:05:35+00:00Yikes, roughly on par with GLM 5.2 at 5x the price
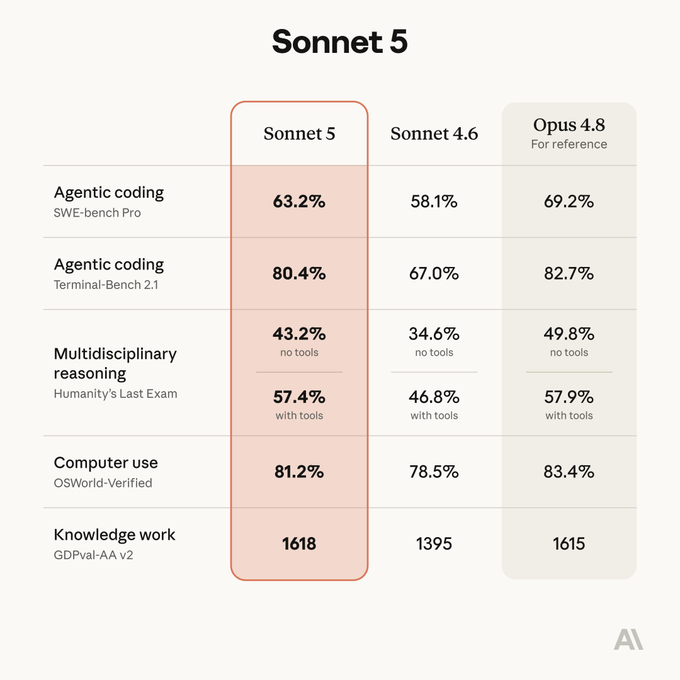
AI visual analysis: A comparison chart titled "Sonnet 5" showing benchmark performance across Sonnet 5, Sonnet 4.6, and Opus 4.8 (for reference), with Sonnet 5 achieving 63.2% on SWE-bench Pro, 80.4% on Terminal-Bench 2.1, 43.2%/57.4% on Humanity's Last Exam, 81.2% on OSWorld-Verified, and 1618 on GDPVal-AA v2 — figures that undercut the "5x the price" claim since Sonnet 5 is Anthropic's mid-tier model priced well below Opus 4.8 ($15/$75 per million tokens vs. $15/$75 for Opus 4.8 at the time of release), making the comparison to GLM 5.2 a value critique rather than a pricing one.
· 2026-06-30T07:43:23+00:00Assuming I need $7000 to get a rig of 3090s to efficiently run GLM-5.2 locally, this would translate to ~5 years of a frontier Max 5x subscription. Local models are a fun, futuristic dream, but nothing else. Sad.
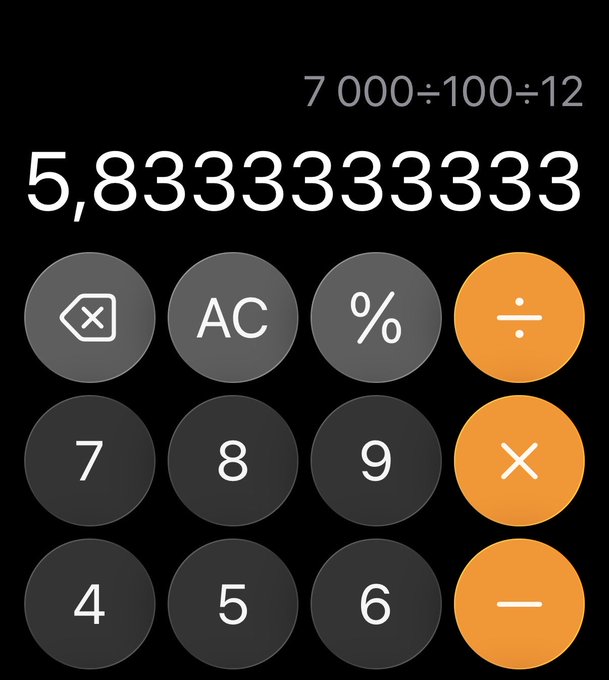
AI visual analysis: The image shows a calculator app displaying the result of 7,000 ÷ 100 ÷ 12, which equals 5.833333333. This calculation illustrates the post's point: dividing $7,000 (the cost of a 3090 GPU rig) by $100 over 12 months shows that running a frontier AI model locally would cost roughly 5+ years of subscription fees compared to a cloud service.
· 2026-06-30T17:44:42+00:00Come on, let's claim the free GLM-5.2 API key. => glm.babel.town Base URL: api.babel.town/v1 Just spam away, you'll get it eventually
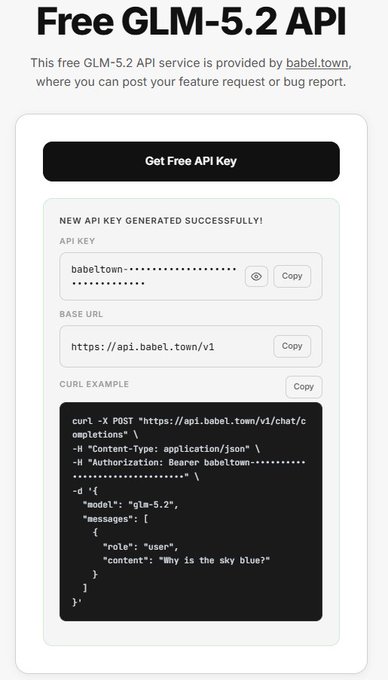
AI visual analysis: A screenshot of the GLM-5.2 API key generation page from babel.town, showing a successfully generated API key, the base URL "https://api.babel.town/v1", and a curl command example. The image directly illustrates the steps mentioned in the post for claiming a free API key at glm.babel.town.
· 2026-06-30T05:02:48+00:00Have you switched to using GLM? I know many in San Francisco who already have.
· 2026-06-30T20:34:20+00:00Almost opus 4.8 is the GLM 5.2
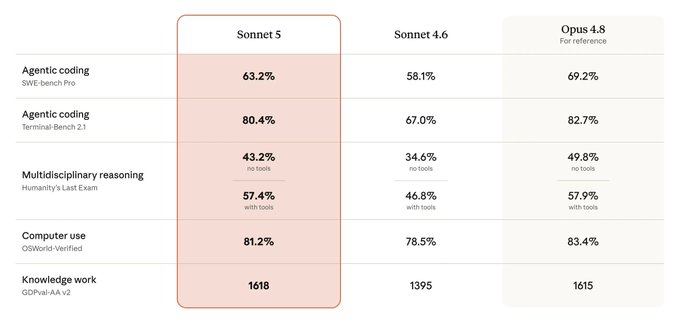
AI visual analysis: A comparison table showing performance benchmarks for Sonnet 5, Sonnet 4.6, and Opus 4.8 across categories like Agentic coding (SWE-bench Pro), Agentic coding (Terminal-Bench 2.1), Multidisciplinary reasoning, Computer use, and Knowledge work.
· 2026-06-30T21:06:56+00:00Breaking GLM 5.2 news it is up and running on 5 asus gx-10s (gb10 chip) all 744 b params and 1m context. That being said it took forever and a ton of hoops to get this up and running. Now the down side we are at blazing 4.2 tokens per second prior to starting all the
· 2026-06-30T00:37:03+00:00So, I'm nearing $1000 in GLM-5.2 usage. CHEAPER.
· 2026-06-30T15:43:14+00:00GLM-5.2 BEING FOSS IS A FEATURE, NOT A BUG it's funny to see Craig Smith on Forbes (cc @craigss @Forbes ) ranting on how "the bad guys now have a model as powerful as mythos" first, because by "bad guys" he means the people: you and me and everybody else that is not whitelisted
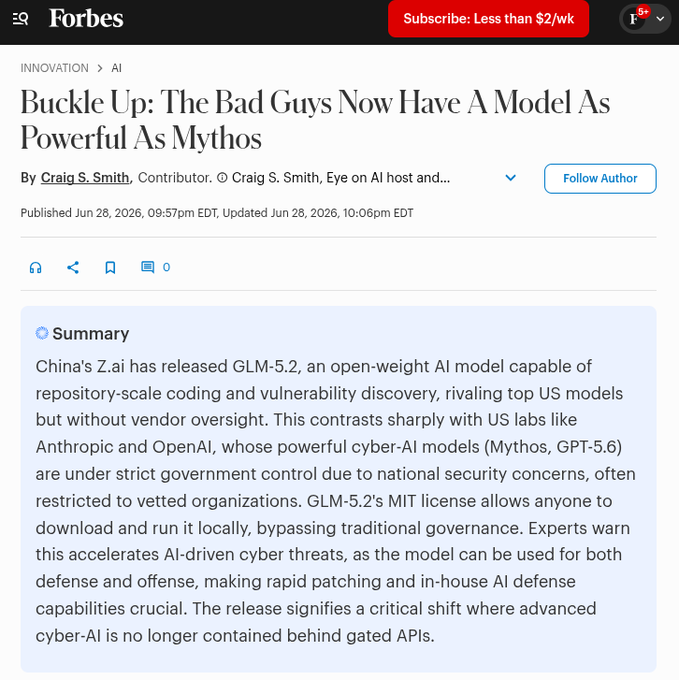
AI visual analysis: A Forbes article titled 'Buckle Up: The Bad Guys Now Have A Model As Powerful As Mythos' by Craig S. Smith about China's Z.ai releasing the open-weight GLM-5.2 AI model capable of repository-scale coding and vulnerability discovery.