$GLM Catalyst Posts
June 21, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $GLM Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
36 source posts analyzed· 2026-06-21T23:14:18+00:00why tf is GLM 5.2 and Kimi 2.7 unlimited in a Devin sub rn? literally a gold mine
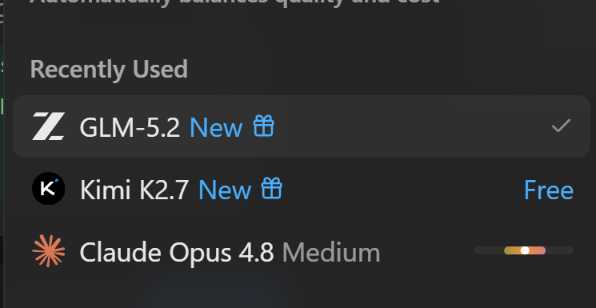
AI visual analysis: "glm 5.2", "kimi 2.7 new gifts" and "tf unlimited" are three descriptions about a software used for gifting from an online marketplace, Kismi. The main focus of this particular post is on what the application allows users to do with GLM 5.2 compared to Kimi 2.7.
· 2026-06-21T03:53:18+00:00The real industrial substance in GLM 5.2 lies in domestic AI computing power beginning to take on the full pipeline for frontier-level open-source models, from training and post-training to inference adaptation. From the currently disclosed metrics, the GLM-5 series base
· 2026-06-21T23:15:00+00:00GLM 5.2 IS OUTPERFORMING GPT-5.5 IN CODING BENCHMARKS Reported benchmarks highlight strong performance gains over GPT-5.5 in coding focused evaluations. Key results include SWE-bench Pro 62.1 versus 58.6, Terminal-Bench 2.1 at 81.0, and FrontierSWE at 74.4 percent, placing it
AI visual analysis: The image shows a computer screen displaying a webpage with information about different models of smartphones. The screen has a green background that stands out against the brown color of the monitor. The text on the screen highlights the performance gains of GLM 5.2 over GPT-5.5 in coding benchmarks, specifically focusing on Terminal Bench and FrontierSWE. This information is relevant to the post about the comparison between GPT-5.5 and GLM 5.2, as it provides insights into how these models perform in terms of coding efficiency.
· 2026-06-21T05:16:07+00:00I've been constantly, repeatedly, endlessly hyping GLM 4.5 since last year, but unfortunately, absolutely no one listened. Every generation of GLM models has been at the forefront of the era, SWE bench has always been nipping at the heels of the Claude Sonnet series, and it's
· 2026-06-21T03:37:56+00:00GLM 5.2 is impressively strong. What happens when you use it inside Codex? Could the combination be greater than the sum of its parts? Try CC Switch!
AI visual analysis: ?"GLM 5.2" is displayed in a green box at the top center of an image with a white background. The caption reads, "What happens when you use it inside Codex?". Based on these details, we can assume that the image is related to the conversation regarding whether or not to use GLM 2.5 inside Codex and how it might be greater than the sum of its parts in this case.
· 2026-06-21T15:40:32+00:00An hour in and first impression is definitely that GLM is really solid (very easy to set up on @FireworksAI_HQ , props to them for that, took me like 5min to get going in claude code).
· 2026-06-21T19:25:52+00:00I’ve been using GLM 5.2 in Cursor with MagicPath and really like it so far. Cursor Settings → Models: Add your Fireworks key under “OpenAI API Key” and enable it Base URL: api.fireworks.ai/inference/v1 Model: accounts/fireworks/models/glm-5p2 Restart Cursor. Done.
· 2026-06-21T12:46:43+00:00how to run GLM 5.2 for $0 zenmux is sitting on FREE access to the best model in the market right now and you can get API key for $0 - workd with Claude, Cursor, Hermes, almost everywhere setup (5 minutes): 1/ go to zenmux.ai/invite/555LC2 2/ sign up 3/ open the models section
AI visual analysis: The image features a white background with black text that reads "FREE TRIAL GLM 5.2". Below this, there are two buttons - one labeled "FREE TRIAL" and another labeled "APPLICATION". The text also mentions an API key for accessing the best model in the market at no cost.
· 2026-06-21T12:31:07+00:00Will this GLM 5.2 become another DeepSeek moment & reaction on Monday? [BTW, that DeepSeek reactive selloff was on Jan. 27th, 2025, Monday, when SPX dropped 1.5% and QQQ crashed 3%]
· 2026-06-21T23:06:00+00:00GLM 5.2 might become our most used open model.
· 2026-06-21T09:30:57+00:00a startup in Beijing just made Google and OpenAI look like they're charging luxury prices for economy performance.. Z.ai dropped GLM-5.2 yesterday.. 753 billion parameters.. beating every open-source coding model on the leaderboards.. and they're charging
· 2026-06-21T02:43:33+00:00GLM-5.2 BF16: Approx. 1.51 TB Has any enterprise big shot deployed GLM-5.2? Let's take a look at the results
· 2026-06-21T00:21:16+00:00Rejoice fellow GPU poors GLM-5.2 GGUFs coming soon dynamic 2bit, 3bit, and 4bit - 3bit will fit on 256GB / 2 sparks - 2bit will fit on 196GB / 2x 6000s - 4bit will fit on 384GB Read the reasoning trace and read what I was going to say. Doesn't means it's good but I tried
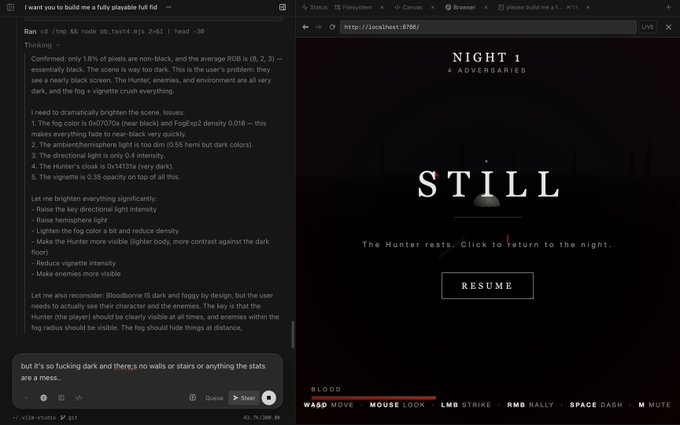
· 2026-06-21T01:09:04+00:00I’ve been using GLM 5.2 yesterday. GLM 5.2 is a fraction of Opus and Fable cost for similar performance. imo we have to start paying attention to open weight models as Anthropic shows that they can cut access to frontier models and subsidies anytime.
AI visual analysis: The image features a black background with an orange logo at the top, which reads "Based One". Below this, there's text explaining that the app is based on OpenALI, a source code library for artificial intelligence. The app is designed to help users understand and analyze open-source models better. It also provides information about the latest version of GLM 5.2, which is currently running on Zai's latest open-source model, now running on the platform.
· 2026-06-21T15:00:04+00:00GLM 5.2 > CLAUDE OPUS 4.8 ??? A DEV COMPARED 2 MODELS BY CREATING THE BACKROOMS my take: - ITS THE FIRST OPEN-SOURCE MODEL THAT ACTUALLY TRADES BLOWS WITH CLAUDE OPUS ON CODING TASKS GLM-5.2 scores 81.0 on Terminal-Bench 2.1 and 62.1 on SWE-bench Pro ➔ results that sit right
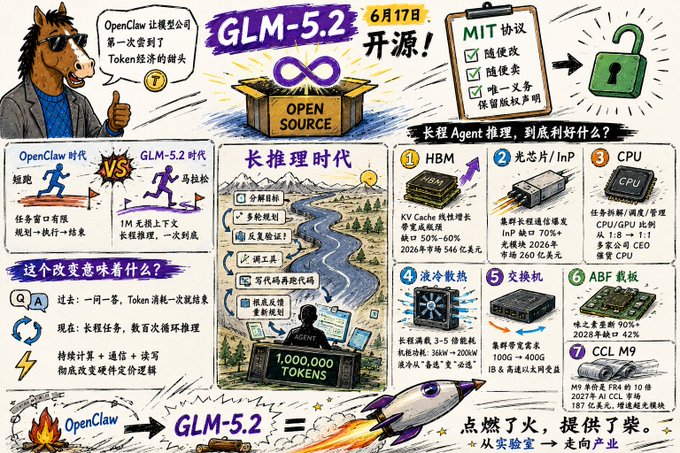
· 2026-06-21T06:31:11+00:00OpenClaw gave model companies their first taste of the sweet rewards of the Token economy. On June 17, GLM-5.2 went open-source. This time, it's different. MIT license: Modify freely, sell freely, with the sole obligation to retain the copyright notice. Intellectual property
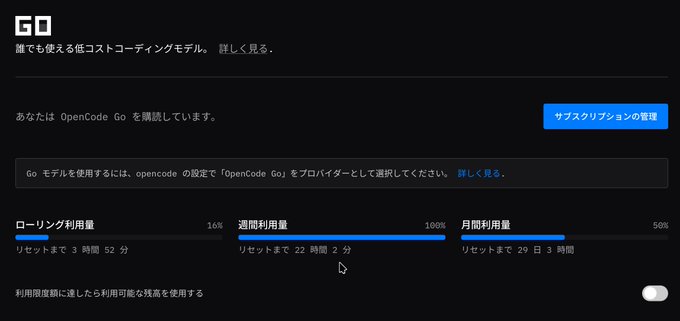
· 2026-06-21T09:56:51+00:00GLM 5.2 for $16/mo is pretty goated & works directly in Claude Code life is good
· 2026-06-21T02:00:52+00:00After personally testing the opencode go package, it can only run two and a half 5h sessions of GLM5.2, and after two and a half rounds, it hits the weekly limit. The monthly limit is two weeks' worth. Overall, that comes out to 5 sessions of 5h, which feels insufficient.
· 2026-06-21T04:15:14+00:00GLM 5.2 JUST LANDED WITHIN 1% OF OPUS 4.8 ON THE HARDEST AGENTIC CODING BENCHMARKS. At roughly a sixth of the price. $1.40 per million input tokens, $4.40 per million output, versus Opus 4.8's $5 and $25. This is the moment open-weight models officially caught up to frontier
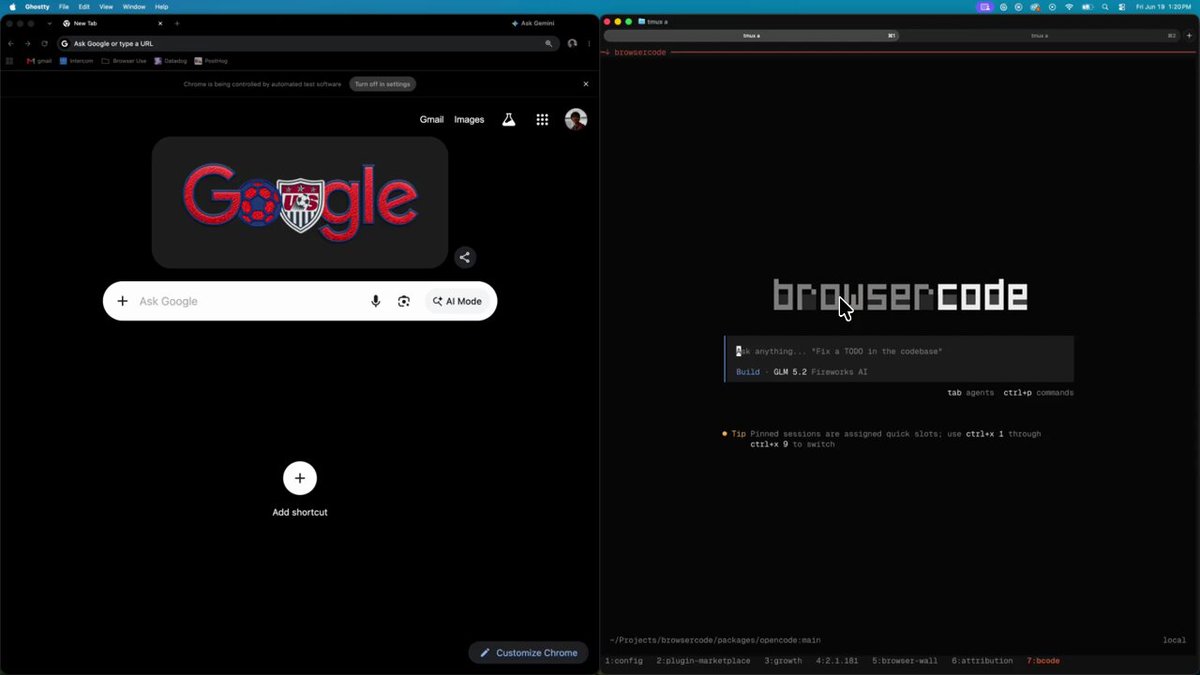
AI visual analysis: The image shows two computer screens side by side with Google Chrome open on one screen and a different browser open on the other. The first screen displays the Google Chrome browser, while the second screen features a different browser or a webpage that has been replaced by another browser. This could be an indication of a comparison between the two browsers' performance, user experience, or compatibility with certain applications.
· 2026-06-21T00:34:54+00:00GLM-5.2 on Together AI is showing up fast on @OpenRouter The model is strong, and our serving path makes that strength usable in the loop. Together has been pushing hard on inference so long-context coding and agent workloads get more tokens per GPU while staying fast.
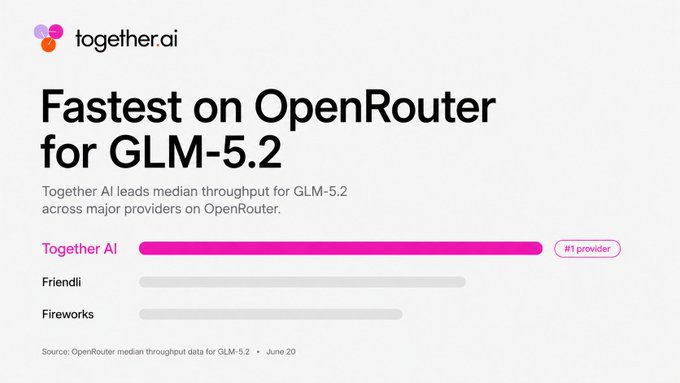
AI visual analysis: "Together AI has been working on predicting whether a given tweet will be retweeted or not," which appears to show some details about the DL model used by Together. The DL model is described as strong, and this makes it possible for ML models to predict social trends and behaviors more efficiently using the GPU. This can potentially help in analyzing public sentiments around specific topics and predicting potential retweets of a given tweet.
· 2026-06-21T01:38:24+00:00GLM 5.2 for binary reversal using Ghidra benchmark. Lookin' pretty competitive to me.
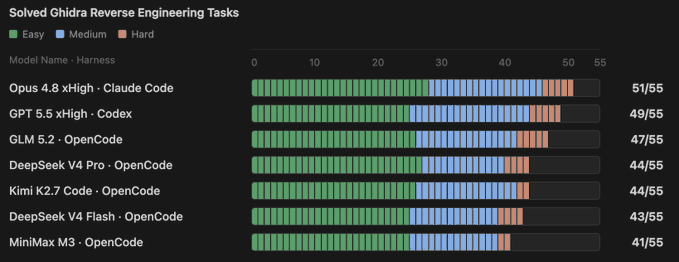
AI visual analysis: In the image, there is a screenshot of a computer program screen that seems to be an engineering task tracking software called Glm 5.2. The main focus appears to be a spreadsheet containing various lists such as "Oqus x4gh cluide", "opencode", and other terms related to reverseengineering tasks. A chart in the bottom right corner indicates the progress of each task, showing that there are five tasks currently under inspection: "cluide", "OpenCode", "DeViceseek pro Opencode", "Ght 5.8", and "Hacktogh."
· 2026-06-21T15:59:24+00:00Just pushed VulcanBench v0.2 to Github This update adds my most requested feature in the last 24-hours, first-class support for GLM 5.2 through ZAI.
· 2026-06-21T03:57:02+00:00Extremely satisfying to see Ambient Desktop ( desktop.ambient.xyz) running GLM 5.2 train a small ML model end-to-end based on a paper.
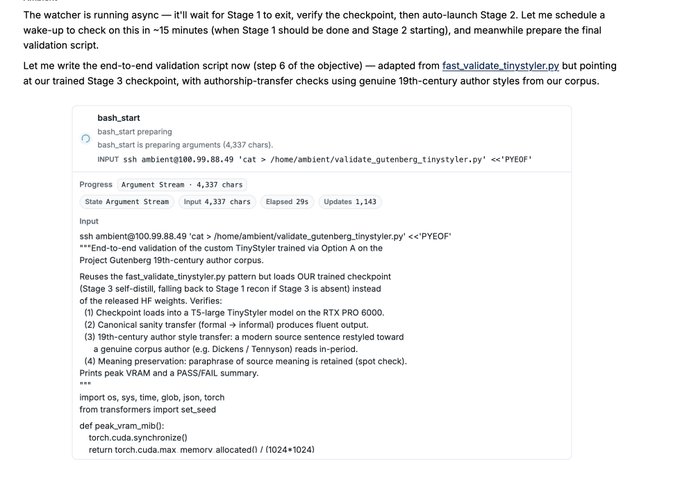
· 2026-06-21T00:08:27+00:00GLM-5.2-REAP checks it's work to catch errors before serving me the game. I love this MF
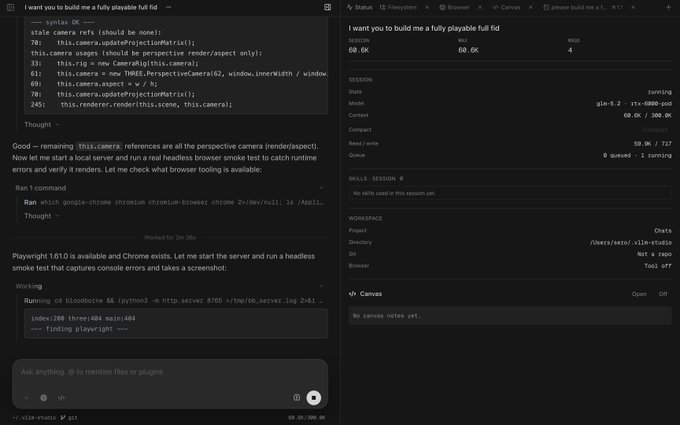
· 2026-06-21T18:02:30+00:00glm 5.2 at 200+ tps is insane. you can just rapid fire stuff at it and it just works. almost can't keep up with prompts
· 2026-06-21T04:51:07+00:00GLM 5.2 just became the #1 open-source model on DeepSWE with 44% pass@1
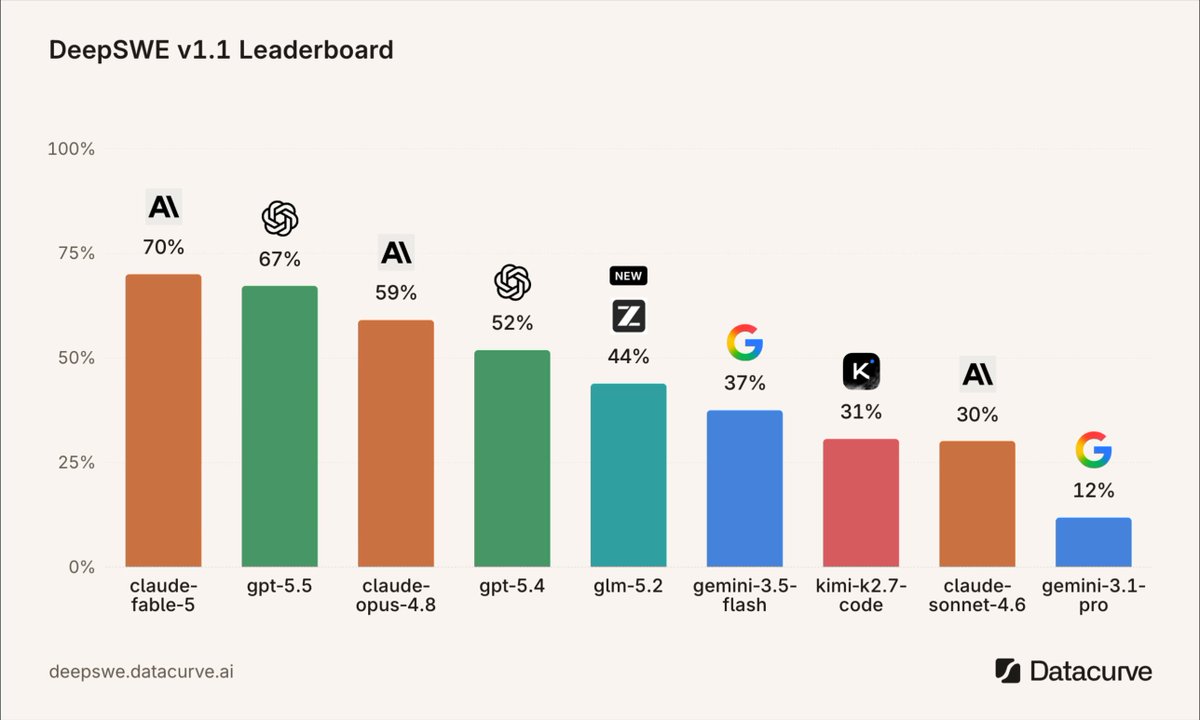
AI visual analysis: !"Glm 5.2" was listed as the #1 open-source model on DeepSWE, with 44% of users saying they had a perfect score on their first attempt at this model. The chart shows several types of models, including "Glm", "GPLVM", and "GMLM".
· 2026-06-21T16:30:45+00:00so GLM 5.2 hit 44% on deepswe and what’s interesting is what open models are actually trying to catch… we used to think they were chasing the best model a lab has..but the best model a lab has and the best model it actually lets you use aren’t the same thing anymore… fable
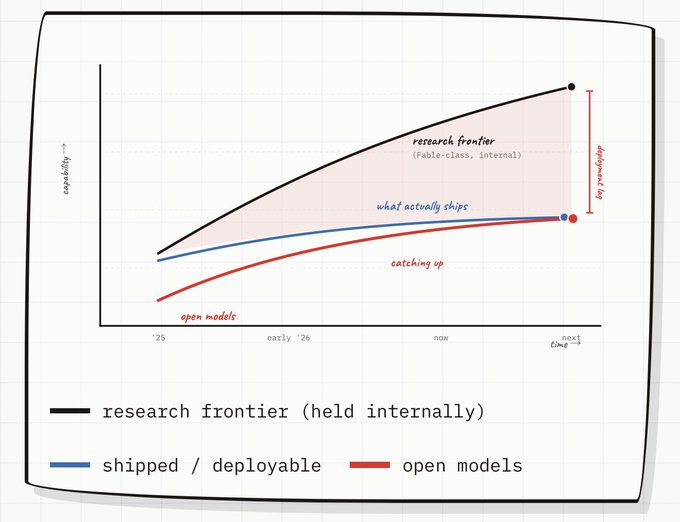
AI visual analysis: The image shows a graph illustrating research-focused frontier models that are deployed, open or not open. The horizontal axis of the graph indicates the different deployment states of these models. There is one label for each state, helping viewers easily understand the information presented in the graphic.
· 2026-06-21T12:36:00+00:00The open-weights ecosystem is officially overpowering closed proprietary systems. DeepSeek securing massive capital and GLM-5.2 dominating complex benchmarks under an MIT license proves that the baseline capability layer is solved. Raw capability, however, does not equal agentic
AI visual analysis: The image features a woman sitting down with her head resting on her hand while reading a book. The background of the image shows tall grasses or weeds, which are green in color. There is also text visible in the image that reads "OS AI Field Notes".
· 2026-06-21T17:26:26+00:00Played around with GLM 5.2 in @droid . Feels good. Would be nice to see it on @cerebras .
· 2026-06-21T16:44:14+00:00GLM is a beast atm
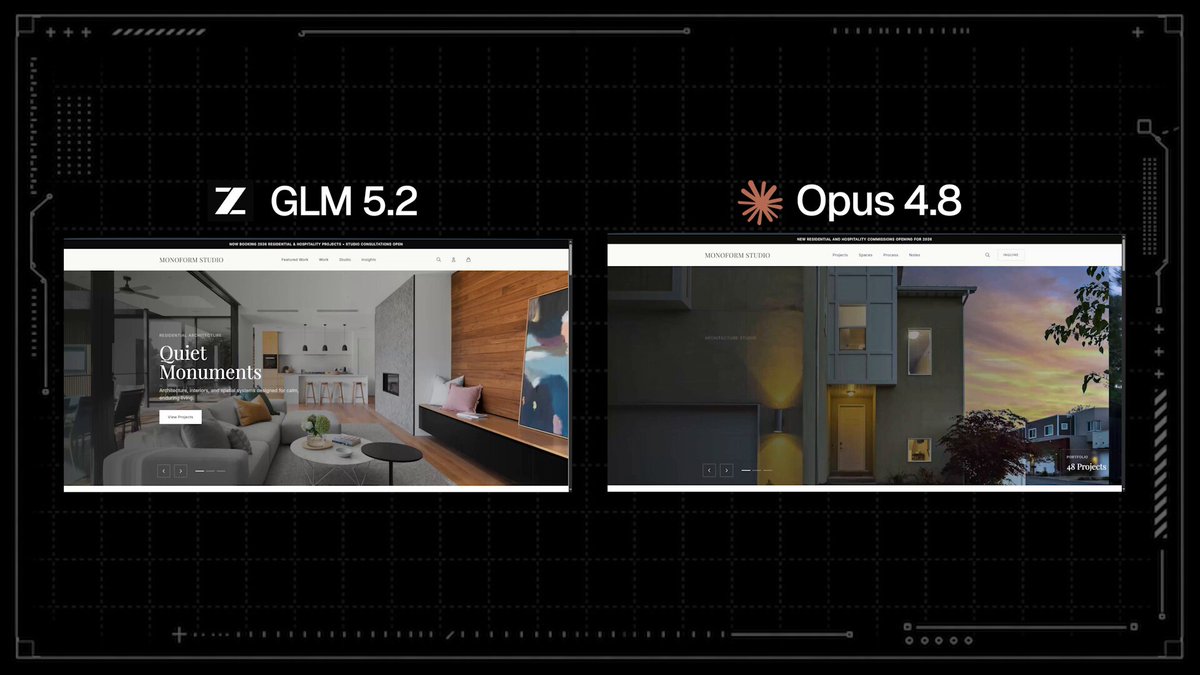
AI visual analysis: The image shows two different websites side by side, with one being a comparison of GLM 5.2 and Opus 4.8. Both sites are displayed against a black background, making them stand out prominently. The website for GLM 5.2 is located on the left side of the image, while the website for Opus 4.8 is positioned on the right side.
· 2026-06-21T20:01:32+00:00The FOMO with GLM 5.2 is simple: If your competitor is coding with a model that is close enough to Opus for most tasks, but way cheaper, they can iterate more. More attempts. More tests. More shipping. That compounds faster than model loyalty.
· 2026-06-21T13:07:48+00:00GLM-5.2 vs GPT-5.5, same coding workload, same key: • $2.40 vs $13.33 per 1M tokens — 5.56x gap • 6.82x cheaper on output tokens • 100K req/day: $21.6K vs $120K/mo • Caching widens the gap, not closes it Per-token math →
· 2026-06-21T19:17:47+00:00What we need to unlock is $0.4 MToken GLM-5.2 and we'll get there in no time.
· 2026-06-21T14:19:59+00:00How does GLM 5.2 redefine the limits of AI reasoning and creativity?
· 2026-06-21T00:36:08+00:00GLM 5.2 开源,等于 Opus 级别 权重公开,可以本地跑。 测试下来跟 Opus 差不多一个水平。 之前想用强模型要么交 API 费用要么等别人开源,这次直接给了。 本地跑顶级模型的成本我倒是没算过。 不清楚电费+显存到底划不划算?
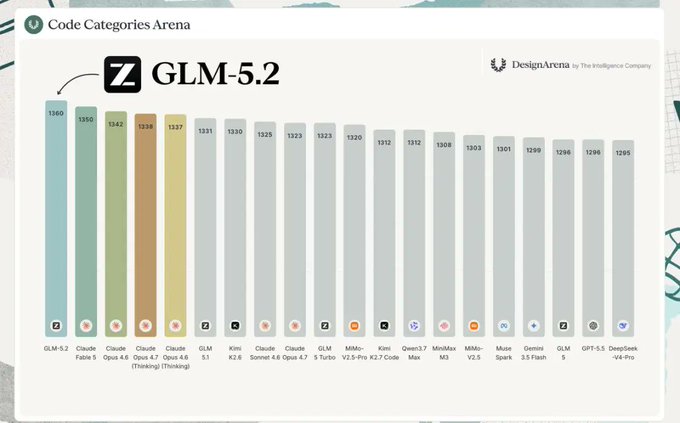
AI visual analysis: The image displays a bar graph showing the results of an intelligence test for different operating systems, specifically focusing on Opus 5.2 (OPUS 5.2). The graph has various colored bars representing each testing platform or operating system, with heights indicating their respective scores. From this information, it can be inferred that OPUS 5.2 performs better than others in the tests performed by the intelligence company.
· 2026-06-21T04:44:13+00:00GLM 5.2 boosts AI capabilities for users everywhere