$0G Catalyst Posts
August 15, 2026Single-day social intelligence recap and verified catalyst posts · ← Back to $0G Profile · Market Rankings
💬 Curated Viral Posts & Community Evidence
4 source posts analyzed· 2026-08-15T17:18:49+00:00Web2 devs: "Our data is safe on AWS bro trust me." Us: Literally mathematically private and verifiable onchain Stop coping, start computing:
· 2026-08-15T01:57:49+00:00Ask a question, get a trade. @zia_finance is a natural language DEX live on 0G, and their $0G liquidity incentives just switched on. 5 boosted pools, rewards paid in $0G.
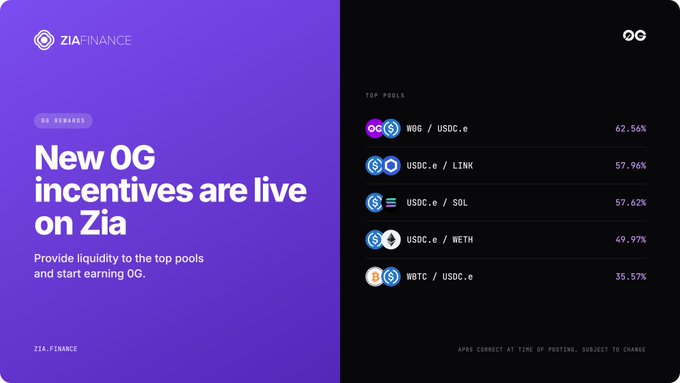
AI visual analysis: Zia Finance announces new OG rewards across five boosted pools, with yields ranging from 35.57% (WBTC/USDC.e) to 62.56% (WBG/USDC.e), directly promoting the 0G liquidity incentives mentioned in the post.
· 2026-08-15T00:56:25+00:00Glm 5.3 now available on pc.0g.ai It improves coding capabilities vs 5.2 by 50%!
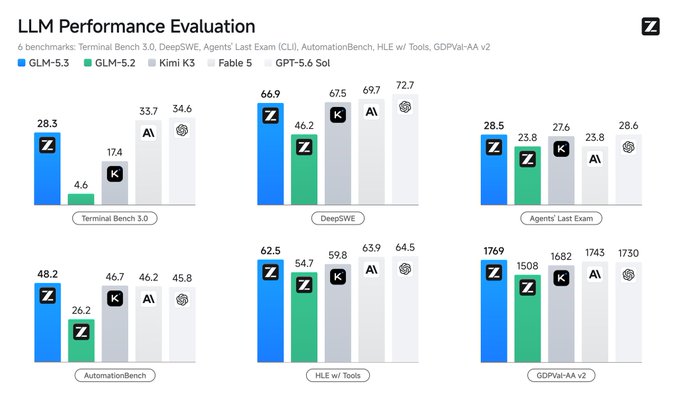
AI visual analysis: The image shows an "LLM Performance Evaluation" chart comparing four models—GLM-5.3, GLM-2, Kimi K3, and GPT-5.6 Sol—across six benchmarks (Terminal Bench 3.0, DeepSWE, Agents' Last Exam, AutomationBench, HLE w/ Tools, and GDPVal-AA v2), with GLM-5.3 scoring 28.3, 66.9, 28.5, 48.2, 62.5, and 1769 respectively. This visually supports the post's claim of a ~50% coding improvement, as GLM-5.3 dramatically outperforms GLM-2 on Terminal Bench 3.0 (28.3 vs 4.6) and DeepSWE (66.9 vs 46.2), the most relevant coding benchmarks.
· 2026-08-15T15:42:41+00:000G Ecosystem is now 0G Builders. The home for everyone shipping on 0G. Expect events, guides, builder showcases, network updates, and the AI news that matters to devs. Start building: build.0g.ai
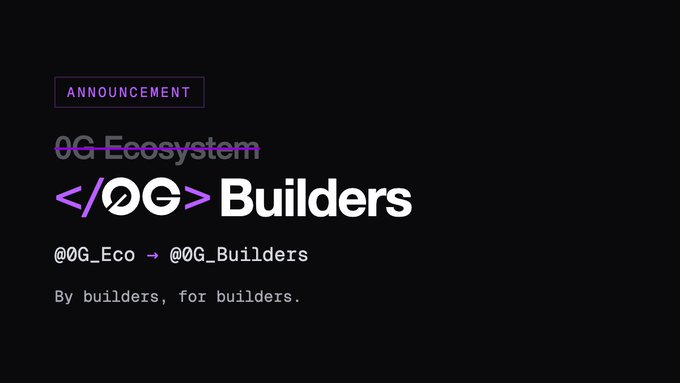
AI visual analysis: A black announcement graphic with purple and white text reading 'ANNOUNCEMENT', '0G Ecosystem', '</0G> Builders', '@0G_Eco → @0G_Builders', and 'By builders, for builders.'