$ZEROTRACE
StableSnapshot Window: 2026-09-25 02:40 UTC · ← Back to Crypto Overview
Tracked Posts
1
Total Impressions
162
Total Likes
16
Retweets & Quotes
0
Comments
11
Social Momentum Summary
Total Engagement - Comments: 11, Retweets: 0, Likes: 16, Impressions: 162
Verbatim Community Citations & Social Evidence 1 source posts analyzed
Serving Llama 3.3 70B on H100 at 8K context and batch 32: FA2 gets you to about 12,000 tok/s. Add FlashAttention-3, then stack FP8 attention on top, and the same setup reaches about 21,000 tok/s, a 1.75x jump from software alone. The version floor to get there: CUDA 12.3+,
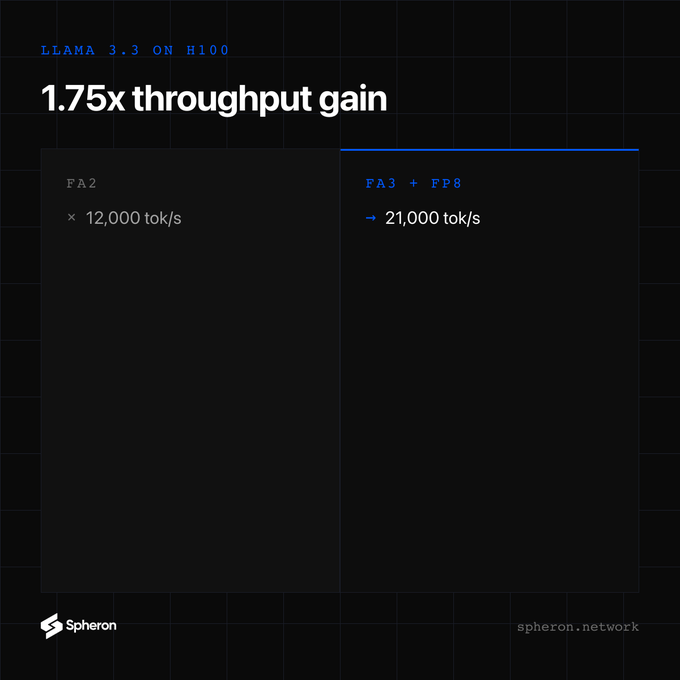
AI visual note: An infographic from Spheron Network highlighting a '1.75x throughput gain' for LLAMA 3.3 on H100, comparing FA2 at 12,000 tok/s to FA3 + FP8 at 21,000 tok/s.