$USDG
Trending UpSnapshot Window: 2026-09-24 04:50 UTC · ← Back to Crypto Overview
Tracked Posts
1
Total Impressions
0
Total Likes
0
Retweets & Quotes
0
Comments
1
Social Momentum Summary
Total Engagement - Comments: 1, Retweets: 0, Likes: 0, Impressions: 0
Verbatim Community Citations & Social Evidence 1 source posts analyzed
Your GPU bill assumes 1,979 TFLOPS. Real decode throughput on Llama 70B is closer to 600. That 1,979 number only shows up with 2:4 sparsity, a trick that skips half the math. Most workloads never trigger it. - Prefill: 90-95% utilization - Decode: 20-40%, mostly waiting on
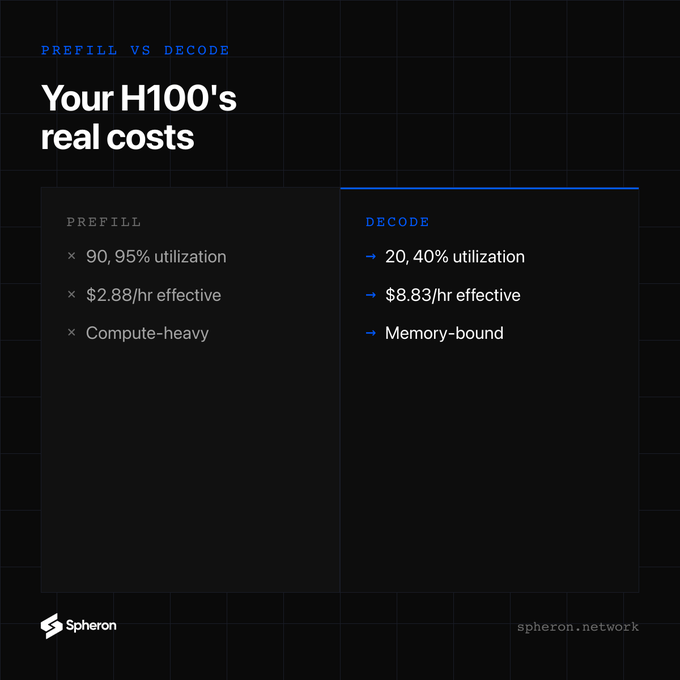
AI visual note: A Spheron Network infographic titled 'PREFILL VS DECODE - Your H100's real costs' comparing prefill (95% utilization, $2.88/hr, compute-heavy) versus decode (40% utilization, $8.83/hr, memory-bound).