$PI
Cooling DownSnapshot Window: 2026-09-17 14:30 UTC · ← Back to Crypto Overview
Tracked Posts
2
Total Impressions
101
Total Likes
5
Retweets & Quotes
0
Comments
3
Social Momentum Summary
Total Engagement - Comments: 3, Retweets: 0, Likes: 5, Impressions: 101
Verbatim Community Citations & Social Evidence 2 source posts analyzed
The arithmetic that decides your GPU shopping list: a 70B model at FP16 needs about 140GB of VRAM. Quantization cuts that 2-4x. Every 1,000 tokens of context adds roughly 0.5-1GB of KV cache for a 7B model, scaling linearly with size. Budget 20-30% overhead on top of the base
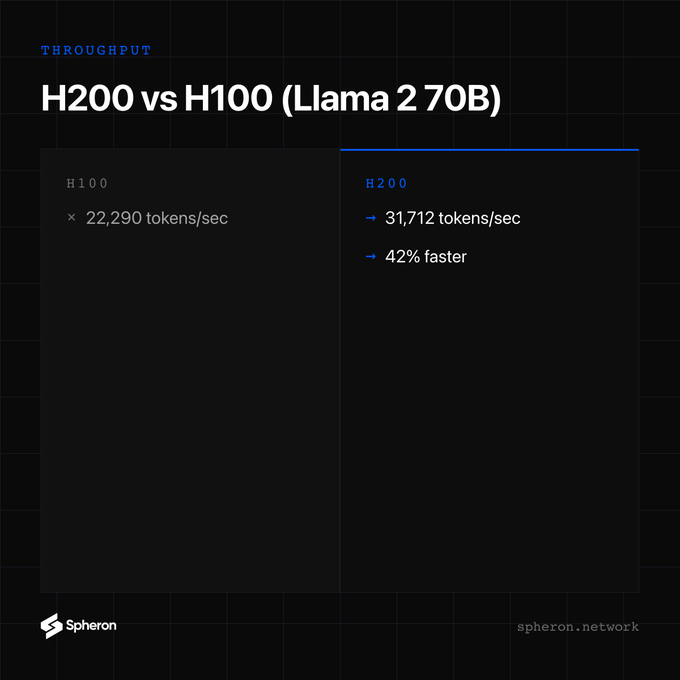
AI visual note: A comparison chart titled 'H200 vs H100 (Llama 2 70B)' showing throughput: H100 at 22,290 tokens/sec and H200 at 31,712 tokens/sec, marking it as 42% faster, by Spheron Network.
the onchain receipts make these claims way easier to verify firsthand