$ZEC
Cooling DownSnapshot Window: 2026-08-28 12:50 UTC · ← Back to Crypto Overview
Tracked Posts
1
Total Impressions
100
Total Likes
1
Retweets & Quotes
0
Comments
0
Social Momentum Summary
Total Engagement - Comments: 0, Retweets: 0, Likes: 1, Impressions: 100
Verbatim Community Citations & Social Evidence 1 source posts analyzed
1233 tok/s on c8 This is getting quite crazy, better than frontier in every way. The only model that makes sense is Grok now. I'm not sitting at 50 tok/s
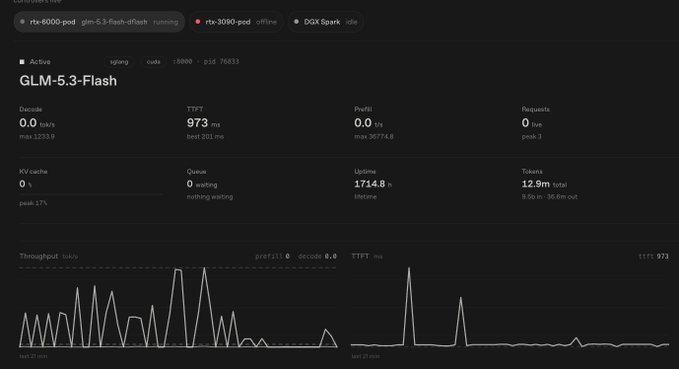
AI visual note: A dashboard screenshot shows the GLM-5.3-Flash model running on rtx-6000-pod with glm-5.3-flash-dflash, displaying metrics including 1233.9 max tok/s decode throughput, 973 ms TTFT (best 201 ms), and 12.9m tokens used across 17:14.8 hours of uptime—confirming the claim of exceeding 1233 tok/s on a single GPU and far surpassing the baseline "50 tok/s" reference mentioned in the post.