$CRYPTO
Heating UpSnapshot Window: 2026-08-19 06:50 UTC · ← Back to Crypto Overview
Social Momentum Summary
Total Engagement - Comments: 9, Retweets: 0, Likes: 12, Impressions: 86
Verbatim Community Citations & Social Evidence 1 source posts analyzed
Fixed a couple VBR accounting bugs on mtp and took a moment to get a quick chart on how much ctx you can get with each quant size, with/without mtp and vision. I have some ideas on getting mmproj-gpu-swap closer to the base MTP price.
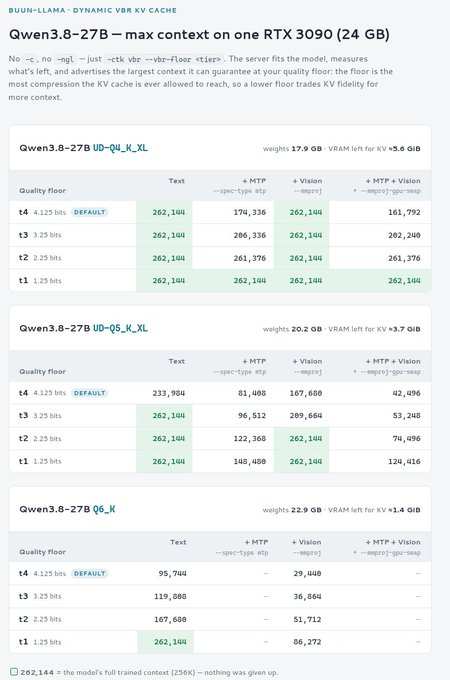
AI visual note: The image is a chart titled "BUUUN-LLAMA : DYNAMIC VBR KV CACHE" showing context length (262,144 = full 256K) available for Qwen3.8-27B models (UD-Q4_K_XL, UD-Q5_K_XL, Q6_K) on a single RTX 3090 (24GB) across different quality floors (t1-t4) for Text, +MTP, +Vision, and +MTP+Vision configurations. It illustrates the author's findings on VBR accounting bugs and quant size trade-offs, supporting their work on maximizing context length for the Qwen3.8-27B model.