$GRO
Fading QuicklySnapshot Window: 2026-08-13 12:00 UTC · ← Back to Crypto Overview
Social Momentum Summary
Total Engagement - Comments: 7, Retweets: 7, Likes: 18, Impressions: 609
Verbatim Community Citations & Social Evidence 1 source posts analyzed
LLMs may be leaving useful work behind every time they generate a token. An LLM does a lot of work internally before deciding what comes next. In standard decoding, only the token it chooses is fed into the next step. The Full-Bandwidth Transformer feeds the internal state
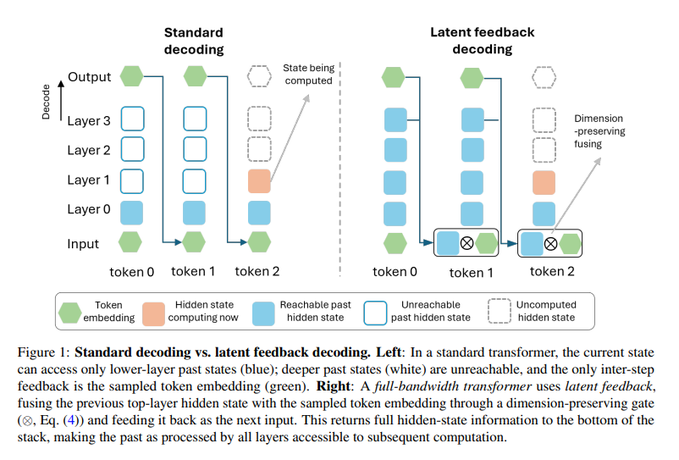
AI visual note: The image compares "Standard decoding" (left) with "Latent feedback decoding" (right) in transformer architectures, showing how tokens flow through Layers 0-3 during decoding, with the full-bandwidth transformer using a dimension-preserving fusion (⊗) gate to feed hidden states back as input, making all layers' past hidden states accessible to subsequent computation rather than discarding deeper-layer information as in standard decoding.