$DOS
Trending UpSnapshot Window: 2026-08-13 09:30 UTC · ← Back to Crypto Overview
Social Momentum Summary
Total Engagement - Comments: 4, Retweets: 1, Likes: 7, Impressions: 351
Verbatim Community Citations & Social Evidence 1 source posts analyzed
A 4B model trained specifically for crypto operations scored 50 on @Velvet_Capital crypto skills benchmark, ahead of Qwen3.5-27B at 45, DeepSeek-V4 at 40, and Llama-3.3-70B at 32. What I find even more interesting is the jump from 23 in the base model to 50 after task-specific
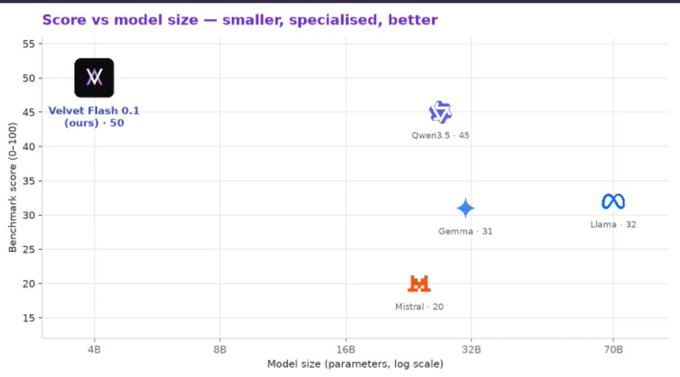
AI visual note: A scatter plot titled "Score vs model size — smaller, specialised, better" displays benchmark scores (0-100) against model size on a logarithmic scale, showing Velvet Flash 0.1 (4B parameters) leading at 50, followed by Qwen3.5 at 45, Llama at 32, Gemma at 31, and Mistral at 20, illustrating how a smaller task-specific model outperforms much larger general-purpose models on crypto skills evaluation.