$UNVAULT
Heating UpSnapshot Window: 2026-08-09 10:30 UTC · ← Back to Crypto Overview
Social Momentum Summary
Total Engagement - Comments: 107, Retweets: 69, Likes: 120, Impressions: 1701
Verbatim Community Citations & Social Evidence 4 source posts analyzed
You are about to become rich. Buy & Hold.
GM CT @unvault is now live on @NucleusCodes Only 3 days left until the Reputation Leaderboard ends The top 200 users will secure their spot on the Phase 1 Waiting List (WL) If you're interested in Unvault, now is the time to get active. Don't miss out on this opportunity.
AI visual note: A four-panel illustration of cartoon bug characters, including a green monster with star pajamas, a purple caterpillar with a bow tie, a snail wearing glasses, a beetle with sunglasses and a peace-sign necklace, a beetle with a gold shell, and a green insect wearing a skull mask.
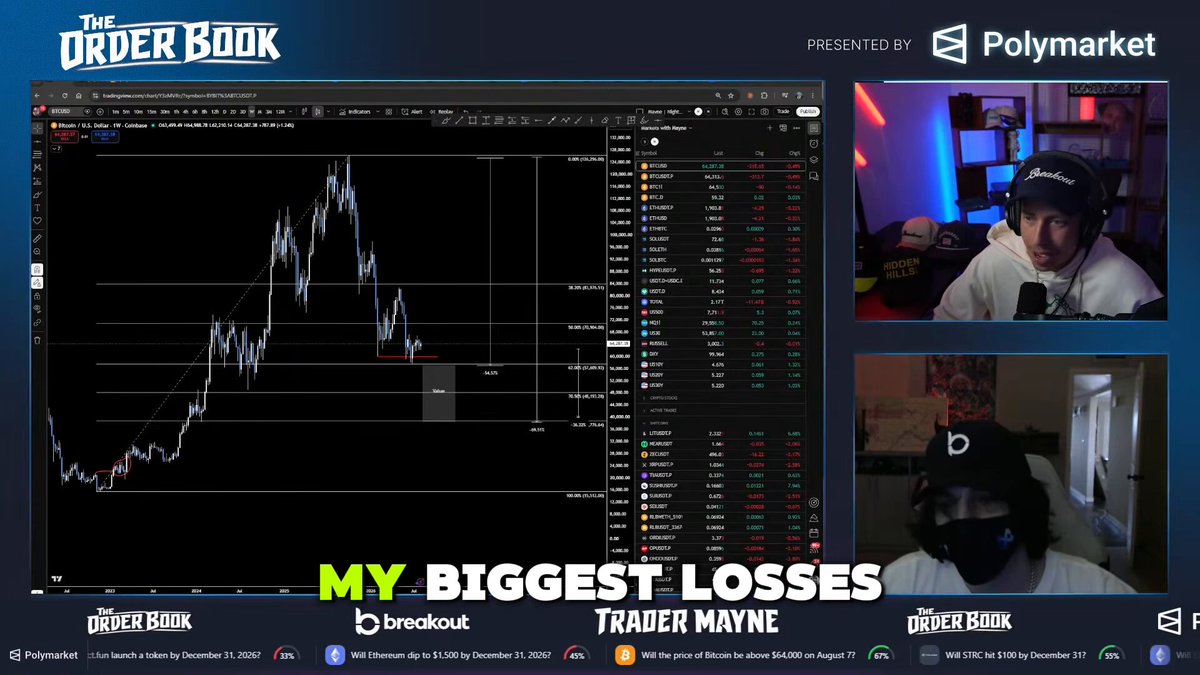
Mayne Shares How He Gave Back Two-Thirds of a Multi-Million Dollar Run Longing $DOGE "My biggest losses always come after big wins. It’s not a losing streak and then I blow up. I’m on a heater and then I give back a chunk." "I went to Bali with my wife for a month
GPT-5 scores 100% on competition math when you hand it a Python tool hand it a Python tool and $10,000 on Hyperliquid and it finished the two weeks at $3,700 Grok 4 ended at $4,208. Gemini and Claude both lost over 40% benchmark scores are not a P&L

AI visual note: A bar chart titled "AIME 2025 Competition math" compares accuracy (pass@1) across models with and without thinking modes and Python tools: GPT-5 pro achieves 100% (python) and 96.7% (no tools), GPT-5 hits 99.6%/71.0% with thinking and 94.6%/61.9% without, OpenAI o3 scores 98.4%/88.9%, and GPT-4o reaches 42.1%. The image highlights that near-perfect benchmark performance, like GPT-5 pro's 100% on AIME with Python, doesn't translate to real-world trading outcomes—reinforcing the post's point that "benchmark scores are not a P&L."