$RIVER
StableSnapshot Window: 2026-08-07 00:40 UTC · ← Back to Crypto Overview
Social Momentum Summary
Total Engagement - Comments: 3, Retweets: 0, Likes: 1, Impressions: 66
Verbatim Community Citations & Social Evidence 1 source posts analyzed
Why is this comparing with Terra and Opus, but not Sol
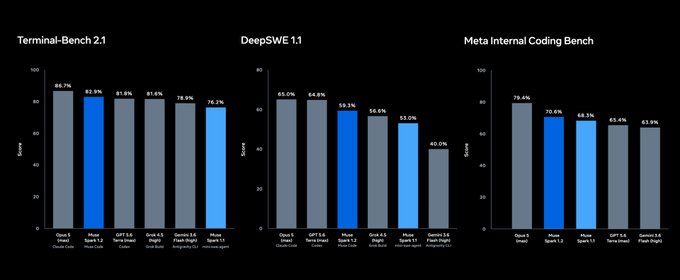
AI visual note: The image displays three bar charts comparing coding benchmark scores: Terminal-Bench 2.1 (with scores ranging from 76.2% to 88.7%, including Opus 4.1, GPT-5.1, and Sonnet 4.5), DeepSWE 1.1 (40.0% to 65.0%, featuring Opus 4.1, GPT-5.1, Sonnet 4.5, and Gemini 3.0 Flash), and Meta Internal Coding Bench (63.9% to 79.4%, with Opus 4.1, Sonnet 4.5, and Gemini 3.0 Flash). The post's question about why Sol isn't included highlights that "Sonnet 4.5 (Terra)" appears prominently in all three benchmarks, suggesting the comparison is designed to showcase a specific company's models against competitors like Opus and GPT rather than including all available models.